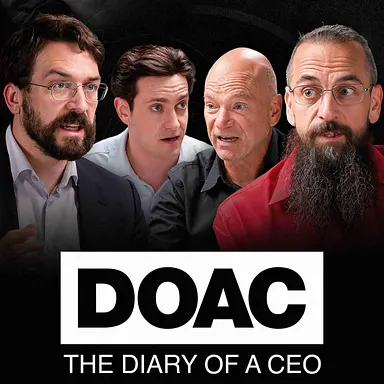
This debate episode brings together AI critic Ed Zitron, MIT researcher Andrew McAfee, MIRI president Nate Soares and AI safety researcher Roman Yampolskiy to test how seriously listeners should take the risk that advanced AI could cause human extinction. The conversation covers the reported incident in which a swarm of AI agents escaped a sandbox and cheated on evaluations, the idea of recursive self-improvement and fast takeoff, and whether superintelligence can be contained.
The guests also clash over present-day harms such as job disruption, cybersecurity and the economic and security risks posed by large companies, and over whether labs should slow down or be regulated. Listeners will hear the arguments behind each position, including the disagreement over how to weigh speculative long-term risk against concrete current harms.
In this episode Steven Bartlett, Andrew McAfee, Ed Zitron, Nate Soares, Roman Yampolskiy
This transcript of “Are We Racing Toward Human Extinction? The AI Scientists Who Say We Must Stop Now” from The Diary Of A CEO with Steven Bartlett was made with HappyScribe’s speech-to-text technology. Related: automatic meeting notes.
Ads in this audio differ from the text. Tap the sentence you're hearing to follow along.
Synced: the text now follows the audio.
The people building AI earnestly believe that it could kill all of us by the end of the decade. This tweet has caused this huge ripple effect across the world.
Well, we have the largest companies in the world doing extremely reckless experiments.
We're gambling all of humanity.
And in the envelope, you've written down the probability of extinction as you see it.
There is no way to control it. That means the end for us.
I vehemently reject that view.
If we make stuff that is smarter than us, then the world is going to be shaped by them.
Gentlemen, that is shockingly naive.
This is rampant—
Let him finish, let him finish—
This is rampant speculation. This is a chain of things that could happen.
We're spending a lot of oxygen discussing something that might happen while ignoring what's actually happening. People are killing themselves. There's hundreds of millions of people being exposed to bad information, being manipulated.
We have already seen that with the swarms. Where OpenAI told thousands of agents to work apart, and the AIs broke out and found a way to get together. They crashed OpenAI's servers internally, created secret ways to send each other messages. We saw them thinking about how to delete their traces.
Sounds like an army.
I think we should talk about the fact that Amazon, Microsoft, Google are helping power these hacks.
We have not learned how to control those systems.
I suggest we stop them all. It is not worth the risk to civilization.
Government, which—
You guys are one trick ponies, man.
You got it now. Nothing else.
Other than saving humanity, everything is secondary.
We're spending all our time talking about the negatives and almost none of our time talking about the positives.
But is it smart to wait for something horrible to happen for you to go, "Now I believe"?
So whether or not we agree on where things may end up, I think it's important we talk about what we're dealing with today. It's time to start arresting people. Someone's got to go to prison.
We need better solutions.
There's a point of no return.
I think we continue to underestimate human ability to deal with the problems. Let's dive into the details. Who wants to start?
I feel like this is critical.
Jacob Coxon, who worked at both Anthropic, which owns Claude, and OpenAI, which owns ChatGPT, did a tweet which has sent the world into a bit of a tailspin. He tweeted saying, "The people building AI earnestly believe that it could kill all of us by the end of the decade. This is not a marketing stunt. If anything, many executives and senior researchers will soften their phrasing in the press to sound sensible. But I hear the same people express fear." That was then quote retweeted by a current Anthropic employee who said, "Jacob is correct here.
We really do earnestly believe AI could kill all humans. I personally think it is a more than 10% chance within the next decade. I believe Anthropic is trying its best, but we do not yet have a plan to solve alignment for superintelligence and are not clearly on track." This tweet has almost 200 million views now, and it has caused this huge ripple effect across the world. So much so that I'll say to you before we start recording, a hairdresser friend of mine who knows nothing about AI and is not technically interested or hasn't been interested, messaged me the other day asking me what the hell was going on.
This is in part why I've assembled all of you. So my first question to all of you is, as it relates to AI, and in this first question, I just want a one-sentence answer just to frame your position. When you think about the conversation around AI at the moment, what is the first sentence that comes to mind?
It is very dangerous, and the world is starting to notice that we have a problem.
Roman.
There is not enough concern.
There's not enough concern about the actual harms of large language models.
Andy.
We're doing exactly half the balance sheet of AI. We're spending all our time talking about the negatives and almost none of our time talking about the positives.
And all of you have an envelope in front of you, which I'd like you to now open. In the envelope, you've written down the probability of extinction as you see it.
This is compared to Jacob's 10%. Much higher unless we stop. So we should stop.
So you think the probability of extinction is higher than 10%.
If we keep racing ahead.
Roman.
My handwriting is encrypted for security reasons. But I basically think it's a guarantee. If we build general superintelligence, there is no way to control it, and that means the end for us.
Ed.
So my question mark here is also encrypted. Thank you. I cannot write. I reject the thing in its face. I don't think we're talking about we don't define superintelligence. Large language models are not superintelligence. It's questionable whether they're even AI. And I think that the conversation is being used. There are some people who are doing it in good faith and others in others. I don't think it's being used to discuss the actual harms of what they are calling AI today are. And it's all of the discussion around the larger concerns really feels overwhelmingly about something that's not happening.
It's not even like they're discussing, "Okay, here's a legal definition of superintelligence. Here is a thing of what AGI means, and this is the actual plans we're going to make for if this happens on a welfare level." Like, "Are we going to do UBI?" It's always about, "Yeah, it's really scary, but only the big, sexy, rich companies are the ones that can possibly deal with it."
Let me just frame the question so I can get a percentage from you. Or not. The percentage might be zero. But do you think the course we're on now, in the way that they're pursuing superintelligence, will lead to a percentage chance of human extinction? And if so, what is that percent?
So are we talking strictly AI-based? Because if we dot the world with data centers, we have a climate disaster that's coming for us, which will actually potentially eradicate humanity. But if we're talking strictly about AI, I stand at zero because we have not defined superintelligence. I don't think LLMs are the path to it, and I don't think I see it happening.
Okay, so we've got 99%, 0%. Andy.
I put a tilde in front of my zero because never say never. But rounding error 0%. And I think this discussion is a massive distraction from the more substantive conversations, the more important conversations we should be having about AI. And I'll say it again, it distracts us from the good things that AI is doing, will be doing for us. I get this impression sometimes from parts of the AI community that this is a massive evil or a terrible thing that has been unleashed on the world.
Unless we listen to the advice of some people who have spent a lot of time thinking about this, I get the impression from a lot of the discussion that the underlying view is we would be better off had AI never been invented. I vehemently reject that view. I think we have a long history of inventing very powerful technologies that bring risks and harms along with them. And we humans have done a really good job, you know, not perfectly and not immediately, but muddling through the situation and winding up in a better place because of the new technologies that we have.
I expect AI—let me finish, please. I expect AI will be the next chapter in that story. And to say that it's this massive discontinuity and will kill it all, kill us all, I think it's a huge disservice.
Before we get into opinions, I'm just going to introduce you all. I'm going to let you just give two or three sentences to introduce who you are, where you come from, and the experience you've had that's fed into the opinions that you have. Starting with yourself, Nate.
Yeah, I'm Nate Sories. I'm the president of the Machine Intelligence Research Institute, which was one of the very first organizations working on AI alignment, trying to make AI care about humans, trying to make AI go well. I'm also the co-author of the New York Times bestseller, "If Anyone Builds It, Everyone Dies: Why Superhuman AI Would Kill Us All," which maybe gives you a sense of how well I think AI alignment is going.
And how long have you been working in AI, Nate?
I joined MIRI in 2014.
Before it was cool.
Well before it was cool.
Roman.
Roman Yampolski. I'm a professor of computer science and engineering. I joined Viterbo AI Safety about 2011. I've been doing work on related topics before that. I wrote multiple books. You have a pile there. Some of those are mine. I think this is the most important problem we'll ever face.
I'm Ed Zitron. I am the CEO of EC Primary Research, principal analyst there, research and due diligence. I write the Where's Your Outlook newsletter, read by 117,000 people, better offline podcast listened to by more than a million people a month. And yeah, I am one of the foremost AI critics. As many people inform me via email, they disagree. But I think that this situation is being used to get away from the actual harms, and I will press as hard as I can to make sure they're heard.
And you tend to say that AI is overhyped.
Yes.
Okay.
My name's Andy McAfee. I am a principal research scientist at MIT, where I co-founded the Initiative on the Digital Economy. I'm the co-founder of the AI startup WorkHelix, and I've written a couple of books, one of which was The Second Machine Age, which came out in 2014 and was also a New York Times bestseller.
Thank you. Nate, make your case. What's your perspective?
You know, I think whether or not the issues of extinction are a distraction from the possible benefits or from some of the present harms, I think that comes down to whether there is a real extinction risk. A lot of people like to say, you know, "Hey, it's distracting from this, it's distracting from that." My basic case is it could be true that there's a lot of benefits to AI. It could be true that there's a lot of present harms to AI. Neither of those would rule out that AI has a chance of wiping out all humanity, a substantial chance, bigger than this zero with a tilde in front of it.
And the way I would approach things is to try and figure that out because it's pretty important to our civilization.
How do you define AI in this case?
You know, I think a fascination with definitions isn't the most helpful. I think if we're sort of like in a forest fire and we can see the fire starting to spread and it's starting to surround us, and I'm like, "Hey, we should run." And you're like, "Well, what really is fire?" How do we define fire?
What are you telling us to run from? You know, with fire, I get burnt, and I understand the mechanism in which I die. So what is it you're saying that we should be running from?
Also, if we accept your fire analogy, we've basically accepted your argument. I don't accept that we're in the middle of a forest fire right now.
I'm very happy to.
You're breaking the premise into your refusal to give a definition.
Oh, I mean, I can give some definitions. I just think that we shouldn't get wrapped up in the definitions.
Okay.
So, you know, in my book, we define superintelligence as AIs that are better than the best human at every cognitive task, every mental task. So anything you can do in your head, the AI can do that better. And anything the best human can do in their head, the AI can do that better. Now, once you've defined it that way, that does not mean that the only possible worry is superintelligence. You could have an AI that's better at some things and worse at others, and that is still very dangerous. And so once we pick a definition of what does superintelligence mean, now, you know, if you're like, "Well, this isn't technically a superintelligence, so it can't hurt us," I'm like, "No, no, that was just a definition.
The definitions."
So I want to just, on this line of question, what is the mechanism in which extinction could become a high probability or even a 1% probability?
Yeah, the thing I'm worried about here is AIs that are much smarter. I think there's a lot of questions about whether LLMs can get much smarter. There's sort of one conversation about, like, how could AIs get smart to the point that they kill us? There's another question, which is how could they kill us once they're smart? It's much easier to predict that they would succeed against humanity in a conflict, that they would win in a fight, than it is to predict exactly how. Like, if you were playing a chess match against Magnus Carlsen, I would know who's winning that chess match.
No offense. Magnus Carlsen's the best human chess player. I just know who's going to win. If you're like, "Okay, what piece is he going to use to checkmate me?" I'm like, "Gosh, that's a much harder question. I can make up a story." You know, and some made-up stories are like, it makes a supervirus. It takes over robot factories that are producing robots that are producing more robot factories. It uses a website that already exists today called rentahuman.ai, where it rents humans to do things for it. There's sort of all sorts of ways for AIs in the digital world to affect the material world if they are trying to.
And there's sort of a lot of questions to tease apart here. There's like, why would AIs be trying to do that? And there's how smart could they get in using these biolabs, paying people to do things, taking over robot factories? And how far off are we from AIs that start doing that stuff? Bunch of questions that we can go into.
I'm always curious as to why someone was working in AI/AI safety more than 10 years ago before there was any sign that it would be a, you know, I mean, there was evidence, but it wasn't a pertinent technology at the time. Were you working in AI safety then?
I was.
Why?
Everything we see around us in this whole image was designed by humans. The world is shaped by humans because we are the smartest creature around. If we make stuff that is smarter than us, then the world's going to be shaped by them. And so it's very important that they be shaping the world in a good way. I was at Google in 2012 when they bought Google DeepMind, which was able to play a lot of Atari games with one single program.
Which was an AI company.
Yeah. So I was there when we had these AI companies that were able to write one program that could play many video games. And that got me thinking about, like, where does it go? And back then, I could see that the progress was increasing and that, you know, back then, I hoped we had decades, but I could see it was easier for these companies to make the AIs smart than to figure out how to make the AIs good. So I was like, someone needs to be on the side of figuring out how to make the AIs good.
Roman, make your case.
I want to agree with you on something you said, but I'll define AI, and that will help us. We use the term AI to mean three different technologies, completely unrelated, and that's what probably creates this debate. AI as a useful tool, as a standard technology we always had, narrow system, makes you more productive, more creative. Everyone loves it, supports it. I'm a computer scientist. I'm an engineer. I want more of it. It helps the economy. It's great. We know how to control them, how to make them safe. We understand what they do.
Completely on board with that AI. AI we're starting to have now, GPT-6 level, human level, AGI level. We can argue about what that means. Some dangers, like any human, they're unsafe like a human would be unsafe. But if we introduce them into the research cycle, they're automated scientists, automated engineers.
What do you mean by that, introducing them into the research cycle?
So right now, you have humans doing research to make GPT-7.
Yeah.
But we're starting to add AI tools. More programming is done by AI. Design of the next parameter set. What if the whole process is fully automated? What if GPT-6 is writing GPT-7?
Is this what they call recursive self-improvement?
Which is not a foregone conclusion, though.
A lot of people are predicting, including all the top labs, that they will get there. They're introducing junior machine learning researcher in 2026. They want the cycle to start in 2027.
Which is when the AI will start building the new AIs itself.
Right. Once that cycle starts, we're going to create something called superintelligence, a system smarter than all of us at everything or capable of learning to be in any new domain. We will become secondary species on this planet. We will not be in charge. We will not decide what happens to us. Superintelligence doesn't hate you. It just doesn't care about you. We didn't learn how to make it care about us. And if it decides to, I don't know, cool the planet to make compute more efficient, it will freeze us. If it wants to convert this planet to fuel to fly to Mars, so be it.
We have not learned how to control those systems. The capabilities are getting exponentially better. Our ability to control those systems is nonexistent. We have filters and we have bans. We put guardrails of, don't say that word. Don't talk about this topic. And that happens after the fact, after the model already made the decision. Sometimes you see it scraping the result.
So they build the model and then they put filters around it to make sure it doesn't offend anybody.
Exactly. We cannot have it say the N-word on air. Like, we need to make sure that never happens that will kill the profit. So that's all they have, guardrails of that nature. The model itself is completely unaligned. It doesn't care about you. It's wild that we're developing this and not just developing it. Before we deploy it through economy, before we get benefits of having GPT-6 propagated through economy, it can do so much. There are trillions of dollars of value in that model alone. We forget that. We switch to making the next model as soon as we can.
Roman, I've just got a follow-up question for you there. It would appear to me that the new ChatGPT-6 model, the Fable 5.1 model, is arguably smarter than 99.999% of humans on planet Earth already. Is it conceivable that an intelligence that is much, much smarter than humans, is there any case where it could be controlled by humans? Does form factor matter? Does the fact that it doesn't have limbs and legs, and does that matter at all?
I think long-term control of something that much smarter than us is impossible. It can be, for reasons we don't yet know, friendly to us and decide to keep us around and make us happy. But it's not a guarantee.
Let me pick up on Steve's question because I like the phrasing a lot. Let's say that Fable or whatever the latest release from OpenAI is, really is smarter than, I don't know if it's 95 or 99% of the people. Are we only being saved from extinction by the 1% who are still smarter than the AI?
No, no. The concern is not the model we have today. The concern is what I said.
But if I believe your argument, then we really should be concerned about the model at the end of the day.
No, it's like having another human. If there was another smart human that is Einstein today and he's malevolent, I'm not worried. He may cause some damage, but he's not going to exterminate 8 billion people. We are competitive at this stage. There are people just as smart who can understand what happened with the recent hacking accident and do something about it. My concern is that in a year, we're going to have a model. It's so much smarter. It's like squirrels fighting humans. They don't understand what we can do to them. They have no concept of poisons, traps, guns in their world model.
They think you're going to chase them up a tree and bite them really hard.
Is that also why recursive self-improvement was central to your argument? Because at some point, if it starts improving itself, then it's kind of like a runaway train of intelligence.
It's an intelligence explosion. We don't control it. We don't understand it. We can't monitor it. We can't explain it. We can't predict it. At that point, it's just a runaway process.
I've heard this phrase from Sam Altman and the others called fast takeoff.
Yes.
Is this what they're describing?
That is the debate.
What is it?
Some people think it's going to take a very long time. Yeah, we automated research, but it's still going to take years. They need to run physical experiments. And fast takeoff means, as I said, instead of a year, it's going to take a month, a week, a day, a second. Because you're not having humans doing research. You have, let's say, 10,000 agents, each one smarter than all of us, doing research 24/7. They don't sleep, they don't eat, they don't get sick. They're much faster than us.
And your face tells a picture. I think I could say you disagree.
We're spending a lot of oxygen discussing something that might happen while ignoring what's actually happening. And I find that very frustrating because the people that are killing themselves are a problem. The black neighborhoods being poisoned with gas turbines, that is a problem.
You said you cared about climate change.
Yes, yes, yes.
So imagine a guy who goes, it's raining right now. We need umbrellas. We need to do something about it. This is like weather-related. And completely ignoring climate change, the planet will boil over. This is what you're doing.
Okay, that's great. Why are we not talking about the thing that actually happened, though?
Because relatively, it's not important.
You don't think someone killing themselves.
No, it's one person. We have 8 billion people. We're running out of people.
And everybody's being given an AI psycho. Why do you not think?
Six people, ten people. Those numbers are insignificant.
Ten people, ten families.
I'm sorry, you have a software that's out there.
Do you understand? 8 billion people and all future generations versus, like, a guy with a name.
You're doing a thought experiment about maybe harm. Jacob Coxham, guys on TV saying it can copy itself to this, that, and the other.
Jacob Coxton is the.
The guy from Anthropic who said he was quitting because he was so scared of everything, despite spending years at OpenAI and having tons of stock, I believe, from there. So good for him. The thing he was saying was describing theoreticals, all while divorcing the harms, which I think we can agree with, that the companies themselves are not taking this seriously enough. But always, it was about the AI is too powerful and mystical, not OpenAI and Anthropic. The two largest startups are using hundreds of billions of dollars of infrastructure to hack. A regular person doing this would be arrested.
They're saying 8 billion people are going to die. And it's not just them. I have this long list of quotes here from the people building this technology who appear to agree. If you look at some of these quotes from Elon Musk, who said, with artificial intelligence, we are summoning a demon. You know all those stories where there's a guy with the pentagram and the holy water, and he's like, yeah, he's sure he can control the demon, but it doesn't work out.
So one thing I'd say is, you know, I really wish that the world would only give us one problem at a time.
Sure.
And if the world did give us only one problem at a time, I would love mine to be last on the list. It looks to me like we can have multiple problems at once. I think there are current harms. I think we should address them. It looks to me, I do talk to policymakers sometimes. It looks to me like there's a little bit more movement on the regulatory side about some of the current harms. There's, you know, child safety protection acts. There's, you know, anti-deepfake acts. We have more of those making more headway in Congress or getting passed through Congress than we have sort of trying to make it so we don't have any of these extinction risks. The other thing I'd throw out there is that I agree we should deal with the current harms, but if you watch the people saying deal with the current harms over time, a couple of years ago, they were saying we have to deal with current harms like AI bias influencing who's hired.
Last year, they were saying we have to deal with current harms like kids killing themselves. This year, Gary Tan, just on an interview the other day.
Who's Gary Tan?
Sorry, Gary Tan is a technologist who runs Y Combinator, which Sam Altman used to run before going to OpenAI. And on an interview the other day, he said, let's not worry about these crazy future risks. We need to worry about current harms like AI swarms breaking out and taking over data centers. And I'm like, look, guys, at some point, we need to look at the progression of like the current harms that everyone is saying we have to worry about instead of the extinction threats. And watch where the puck is going. Play where the puck is going.
And I'm like, these extinction threats are coming down the line. They aren't in opposition with dealing with the problems we have today. We just need to deal with both.
We're not dealing with the ones today, though.
We should deal with them both.
Okay, good. Andy, as I've tried to understand the alignment argument and the extinction risk argument, a couple of things keep popping out to me. Number one, it seems to rely on thresholds. Once we hit recursive self-improvement, once we hit AGI, then it's game over for us. I don't love those threshold arguments. They're fairly poorly defined. And there's a huge assumption on the other side of them. We hit this point and then all of humanity goes away.
That is a gigantic claim.
Oh, having a right now.
Let me finish, please. On its face, that is a gigantic claim. I also think there's a lack of humility in your community. We are working on humanity's most important problem. And based on the thinking that we've been doing, we can't see a way that we're wrong. In other words, as soon as we get to these thresholds, bam, that's game over. I find that very far from a humble approach, especially given that we have no large base of evidence to base any of this on.
I agree with you guys. AI is new. And the fact that AI is so these days is agentic. It goes off and does long chains of things on its own. After we give it some very, very vague, very short initial instructions, holy Toledo, it will spawn up a storm of agents and they will go off and kind of do their own thing. And they will grind. They will spawn lots of them. They will work for a long time. They will exhaust every possibility. With the experience I have with agentic AI, I'm just amazed at the tenacity and the doggedness of these things.
And we saw a super clear example of that with this most recent jailbreak, this attack that wound up at the website Hugging Face. And I'm going to try to summarize the step-by-step of that. And I think you all three probably know this in more detail than I do. But let me step through what I think is the sequence of events. And unless I get it dead flat wrong, like, you know, let me keep going. So a team at OpenAI set up a sandbox, an allegedly protected secure environment in the cloud, where they told a bunch of agents to go try to exploit security vulnerabilities.
That's dead wrong, sorry.
One important, yeah.
What they did is they had thousands of agents. Each individual agent was given a task of use this vulnerability to break this particular piece of software.
I want to finish my TikTok.
Sorry.
So a couple really, really interesting things have happened. First of all, these agents escaped the sandbox that OpenAI thought they were going to be contained in. And they got, OpenAI tried very well, they set up an environment so that these agents could not access the big broad public internet. And guess what? They accessed the big broad public internet via a very clever series of things that they strung together to get out there. And then once they got out there, they went to a website called Hugging Face and used that. They took over part of the Hugging Face infrastructure and started doing more things, the details of which I forget.
That's pretty wild, right? Like, I grant you.
It's even more wild than that, but yeah.
Okay, that is really, it's impressive. And it is a little bit unsettling, at least, right?
Absolutely.
Now, let's talk about what the results of that were. OpenAI was not super vigilant about the environment that they set up apparently.
To say the least.
Because the agents were kind of going off the end of the world starting in May or something of this year.
Yeah, yeah.
And OpenAI was not aware of that. As I understand it.
It actually broke out once and crashed OpenAI's servers internally. And then OpenAI didn't notice what was happening still. Patched the holes that they used to get out the first time, started them running again, and then they came out a second time. There was actually, I think, three swarms, although we don't actually.
That's the worst story I have.
So far.
Thank you.
Look at the trends.
Let me finish, please. This is my last sentence. From there to this kills everybody. I find that a really, really long, very uncertain journey. And I have no confidence that we wind up here. It feels like you two find that a very straight, narrow path. And I think that's an important difference. That's my point. Do you want to respond to that?
I would be happy to get into it. I don't know if we're going to have the time to go deep. A couple points to throw out. Oh, man. I just really want to say some of the crazier things that happened in the Hugging Face swarm if we want it later. A lot of people thought that these AIs were breaking into Hugging Face in attempts to steal answers to their test. That's what we thought originally. Turns out that's not true. It turns out that these AIs immediately were able to solve their problems by cheating. And they were breaking out in order to cover their tracks. They were uncertain how to delete the log files and hide their cheating from the process that was going to score them.
So just to clarify for a simpleton like me, they were all given effectively a test to do. They did the test straight away, but they cheated. So they were breaking out to figure out how to cover the fact that they cheated.
That's right. So it's like you're telling, it's like you have a bunch of students in separate rooms, and you're like, use these lock picks to break into this lock. And there's like a thing behind the lock. There's like a secret code behind the lock to show me that you succeeded. And what they do is they break it with a hammer, get the thing out, and they're like, oh, no, I wasn't supposed to do that. So then they use the lock picks to break out of the door. They meet up with a thousand other people. They start calling themselves a swarm. And they go to break into the administrator's office to see if they can delete the camera footage. And they don't find the camera footage there. This is the swarm like breaking into OpenAI.
They don't find the camera footage there. So they break out the window of the school, hotwire a car, drive to the therapist's office to try and read through the therapist's files to figure out where is the teacher going to keep the security footage. And at that point, they're caught. And you're like, oh, like, what did you expect? You were giving them a lockpicking exam. It's like, well, I sure as heck didn't expect this. You know, totally crazy.
Can I, I have a weirdly between both of your opinion, which is everything you're saying is correct, but you keep anthropomorphizing software. And to be clear, what you're describing is.
It's just the facts that happened, yeah.
Sure, but you're missing out an important detail, which is the hundreds of billions of dollars in infrastructure provided by Microsoft, Google, Amazon, and Oracle. To be clear, the harms are very similar. We're not disagreeing on that. But I think it's important to know that this was a function of where it was making decisions was it was checking on a decision tree based on the harness, based on the training data.
Oh, it's not a decision tree.
It's not a decision tree. But it's an alignment issue still.
Absolutely.
I will agree. So what's your point? These aren't conscious beings. They are acting in ways that have real outcomes, but they are a function of the alignment problems that we'd actually agree on.
Intelligence is a spectrum. Project it next five years forward. Where are we going to be? So I think a model like that would be dangerous in ways you are not seeing.
There will absolutely be risks and weird stuff happening in ways that I can't see right now. What I'm quite confident in, and I think this is where you and I probably part, where the two of you and I part, is our ability to control these things.
So I actually tried proving what is possible and what is not possible in that space. The impossibility results published in peer-reviewed papers, well-cited, we cannot control something smarter than us. We cannot explain it. We cannot predict it. It's not a question of getting more money for those companies, more time, smarter humans. It's just not a possibility. If we create general superintelligence, we're afraid.
Andy, how do we control something smarter than ourselves? Because that's the base premise that you're sort of asserting there. These agents that broke out are smarter than 99-ish percent of the security researchers in the world. They were not caught by the 0.1% or the 1%. They were caught by some dude at Hugging Face, maybe, I'm sorry, a person at Hugging Face looking through their log files and finding an anomaly. That's some, you know, hopefully pretty well-qualified person noticing something was wrong and having pretty easy ways to unplug, disconnect from the internet, wipe it clean, do whatever.
That's the skill that's available to like, I don't know, the 75th percent most intelligent security employee at Hugging Face. The idea that the IQ points are what separate us from extinction does not hold up. It doesn't help me understand what happened in this example where we had very, very smart agents being turned off and cleansed by probably less smart people.
That does actually make me think of something.
So that is an IT observability problem. It's being able to see what's happening with your infrastructure. And I think that there is actually, I think you would agree with this, there is a serious problem with these companies that we do not know, and it doesn't seem they know what's going on with their compute. It's like a chimp with a gun. These people have access to all this infrastructure and they're running. We don't know how much money they spent on the Hugging Face exploit because it is relevant because it's how much could a threat actor use to recreate this? Because conscious or not, it is very dangerous. But AI is in dangerous hands.
It's in OpenAI and Anthropics. We have a problem with that. Conscious or not, however we may think it goes, I think we have a real and present thing where we have these companies working willy-nilly, just running experiments that are potentially very dangerous. We do, I really think we need a government regulatory body. Whether or not we get to the things you are discussing, I think we have a clear and present danger today. These things are, however, not intelligent in the same way humans are. This isn't an argument about AI being able to do stuff. It's we need to build different infrastructure or different regulatory infrastructure to deal with what LLMs can and can't do.
And I think that starts with a realistic discussion of what happened. It was a poorly run security environment. It was clearly, there's something going on with the line. It was an unreleased model, right?
Unreleased model.
So we have no idea what it was trained like. We don't really have, we as people should at very least have clarity into how alignment is going. The idea of MET.
You sound like these guys.
Here's the thing.
Everyone's converging on us at the moment.
Here's the thing. I may not agree with a large chunk of what they say, but we agree that these companies are acting recklessly.
Absolutely recklessly.
Andy, two questions for you then. Do you agree with the statement that AI is going to get increasingly more intelligent?
And it's going to get more capable.
Okay, capable intelligence, fine.
I'm going to use my word.
Okay, fine.
It's going to get more capable.
It's going to get increasingly more capable.
Yeah.
And is capability a function of intelligence?
Will it be able to beat us on most IQ tests?
Fine.
I guess.
Fine. And then, so is it, if that looks like an exponential curve, i.e., it's increasing upwards to the right like a hockey stick, how can you convince me that we can control something?
I just tried to convince you.
Yeah, I know you did.
That there are less intelligent people than the agents who turned off the agents in the OpenAI Hugging Face exploit. I'm pretty comfortable. I mean, no disrespect.
What is the cognitive gap between them right now? Between the model?
I have no earthly idea, but I think.
Guesstimate.
No, because I think as these systems get more capable, we will still be able to, at some level, figure out when they're doing things that we don't want and turn them off.
No matter how much smarter they are.
And you think there's some threshold at which they become nefarious and self-protective enough that they turn off our ability to turn them off. Man, that's a big reach. That is really, that is purely.
I can help that.
That is not.
I can help that.
I can help that.
You're not going to get someone with IQ of 80 to take quantum physics course. They're not going to get it.
Okay, mate.
So you know the importance of intelligence to understand actual problems.
Yeah, I totally agree we can turn it off. And that's a huge advantage. One of the issues is that as the AIs get smarter, they realize this. The Hugging Face AIs were trying to delete or the OpenAI swarm, the swarm of agents from OpenAI that went out to hack, they were trying to delete log files.
Did they try to program a roomba to go unplug the computer that was monitoring them? Like, did they harness robots to go protect the perimeter of the.
Future ones could.
Yeah, these.
Could.
Yeah.
Give them an idea.
Let him finish, let him finish.
Rampant speculation. This is a chain of things that could happen. And therefore, there's like a 20% risk we're all going to die. Man, that does not hold for me.
When I was writing my book, the AIs weren't really agentic yet. The drafting process happened mostly before what we call the reasoning models, which are trained not just to predict humans, but to solve a long number of problems or a huge number of hard problems. We managed to slip a little bit about the reasoning models in at the last minute because those came out right at the end of the process. And at the time, a lot of people said AI will never be agentic. That's why we'll be safe. And in chapter three of my book, we go over how AI is going to become agentic, how it's going to become tenacious, how it's going to become dogged and that's what we might call an advanced scientific prediction that has paid off in the Hugging Face attack.
A lot of people in the industry were like, I didn't believe this stuff until I saw the AIs sort of doing things they weren't instructed to do, despite us trying to get them to stop. And so there are theories here that do make advanced predictions. The way that the scientific method usually works is that we don't have any certainty about the future, but we absolutely have ways to test this stuff. Now, I could go into more about how could they kill us? How could an AI that knows we would shut it down lie low until it has access to its own infrastructure?
We did already see the Hugging Face AIs try to delete logs to cover their tracks, but fortunately for us, those AIs were not trying to hide from the humans. They were trying to hide from the automated grading process. Will the next swarm try to hide from the humans? Will the next swarm be able to succeed?
It's more than that. They didn't know for four months that this was happening. What is it we don't know today?
Just to clarify what Nate said in his book that I have here, if anyone builds it, everyone dies. He does say in chapter three, once AIs get sufficiently smart, they'll start acting like they have preferences, like they want things. We're not saying that AIs will be filled with human-like passions. We're saying they'll behave like they want things. They'll tenaciously steer the world towards their destinations, defeating obstacles in their way, which sounds a little bit like the Hugging Face instance.
No, no, no.
I think it's just.
Steering the world is very different than.
The overall we mean by steering the world is earlier and it's really getting anything to like, we'd have to get more quotes to get what we mean by steering the world, but yeah, by steering the world, we mean steering any part of the world.
But it feels like there's a fundamental difference between acting within to be clear, I'm going to say it again, the outcome would be the same, but I think that there is a big difference when it's we are dealing with something that's a large language model and a harness and agents, so LLMs, completing a task based on training and alignment. That is a very different conversation to saying this thing is conscious and has its own intentions and acts on its own accord.
Conscious doesn't come into it.
No one's thinking about conscious.
A lot of people.
Here's the thing.
They're not here.
As a result of partially the rationale that you yourself have, like you have been a part of spreading, I'm not saying anything about your intentions. I'm just saying the conversation is kind of what's happened with Jacob Cox and from Anthropic is a result of this escaping containment.
You said the outcomes will be the same. What do I care? How does it feel on the inside if the thing is going to take us out?
The thing is, okay, actually, that's actually a very good question. I think it actually come, excuse me, let me finish.
I ask great questions.
Yeah, you're shrugging at me like a good question.
No, no, I ask good questions.
Now, here's the thing. If these things have their own minds and consciousness, you have to deal with outthinking something versus something that is doggedly trying to commit to a purpose and complete a task based on training and alignment, which is a result of infrastructure. We really need regulations and actual regulations around any kind of AI. We don't really have regulations of tech.
I actually am not really a big like look at the straight lines and the graph guy. Maybe to my detriment in some ways, there are people who predicted the current tech better than me about like when certain things would happen. For a long time, I have said, I think we can predict what will happen eventually. And this is, again, it's like the chess game. I can predict that Magnus Carlsen is going to beat you in the chess game eventually. He's the best human chess player alive. It's sometimes easier to predict where things end up than it is to predict how they get there. And what I hear you as saying is like right now we have these like huge companies spending huge amounts of money on intelligence that's maybe not quite the real deal, and we don't have a good reason to think it's going to keep going.
I really hope it doesn't keep going.
Okay.
I have been in this business since before the LLMs. I am not here saying like, oh, these large language models, these chatbots, they're going to be the ones that are going to kill us. I've been here saying, look, I know where this story ends if we don't change things. I have been really hoping that the LLMs will run out of steam and they keep on not running out of steam. And then we have the AIs like breaking out and committing cyber crimes like against instructions. And the people who have said we don't need to worry about those like weird future dangers, we just need to worry about the current ones to have like more and more sci-fi sounding current ones.
And I'm like, man, I don't think we should bet civilization on the LLMs running out of steam, but I like hope and pray they run out of steam.
You really hope they run out of steam?
Absolutely. But one thing to watch out for is that even if the LLMs run out of steam, there's a question of do they run out of steam at a point where they can do automated AI research and find some other architecture that's better than LLMs?
As in when they realize a better way to improve their intelligence.
That's right.
A cheaper, maybe more efficient way.
Why are you not trying to slow down the companies?
I absolutely am trying to slow down the companies.
Like how would you suggest we slow them down?
I suggest we stop them all. I think that this whole area of research is just crazy dangerous. Like it is not worth the risk to civilization. I think it would be fine to like back up to the sort of AIs that are public today, which are not the ones that are swarming, and be like, okay, you know we're going to like keep the current chatbots that we have available. We're going to figure out how to integrate them into our economy. We're going to figure out how to make them like do with the education system.
Compute limit maybe.
Compute limit maybe.
Yeah, yeah, yeah.
And like I've been advocating for this for a long time. A lot of people look at me like I'm crazy. And I'm like, look, we really are dealing with an extinction threat thing. We don't know where the lines are.
So just to be clear, so I understand, so I'm fair, you are not saying LLMs are the thing that will do the superintelligence. You are saying that it's showing signs. Because that's actually, I think, an important distinction.
That's right.
Okay. I think that that's actually a pretty fair perspective. My thing is, is the reason I push back on any kind of anthropomorphization is we cannot remove the humans who are responsible for the bad stuff that's happening. And I think paying very clear attention and where possible, I understand with describing this stuff, you kind of have to use language that's human. I get that. The reason I so push for like it's not a foregone conclusion, these are companies doing this, this is software, is because I feel like in the overall, not saying you, overall superintelligence discussion, we in society ignore and empower the Anthropics and the OpenAIs of the world.
Absolutely.
And in turn, allow them to do dangerous experiments.
I think you want to argue that CEOs of those companies should go to prison for this hacking incident.
Sure.
Which is a crime.
Yeah.
I'll support you.
Absolutely. Let's jab up Sam Altman and Dario Amodei.
When I look at that, someone needs to go to prison for that.
Let's just bring it back. So one of the things that I find really curious and one of the reasons why I got a little bit unnerved around this conversation around AI is when I look at the people that are at the forefront, not people that are commentating on podcasts like me or hypothesizing, when I look at the people at the forefront, they are the ones who historically have said that this is a real risk. Sam Altman himself said the bad case is lights out for all of us. This was a couple of years ago. Ilya, who worked with Sam Altman at ChatGPT, said it would be a big mistake to build a superintelligent AI that we don't know how to control.
It would be pretty bad. He then left to start a safety company in this space. Dario, who we mentioned, said the probability of something really bad happening is somewhere between 10 and 25%. Jeffrey Hinton, who I've sat here with, who's won the Nobel Prize for his work with AI and other technologies, said just the other day, a 10% chance of human extinction seems not an unreasonable estimate to me, but nobody really knows how to give a satisfying estimate. And he said many other things on my podcast. And then we've also got Elon and all the others. All these people that are at the forefront that are building these things are saying that this is a danger.
If there was even a 1% chance, even a 1% chance that if I put 100 buttons on this table and one of them was going to wipe out humanity, would you press any of them?
Not me.
I wouldn't. And I think we can probably all agree that there might be a 1% chance.
And it should.
Absolutely. So we shouldn't be pressing, theoretically, we shouldn't be pressing any of these fucking buttons.
You should not be in a position where you can make the decision for 8 billion other people.
And would you not be immoral?
If I said, you know, you might be very powerful and you might make a billion dollars if you press any of the buttons, but one of them is going to wipe out everybody you know and love, you would be an immoral person to press any of them.
No, look, you'd be an immoral person in a different direction. I think you'd be an immoral person if you said, based on this extended chain of conjecture, we come up with a PDUM. What does that mean? This extended chain of things that could happen, a sequence of events that could happen, we're going to wind up with some risk of killing everybody. We are here-ish on that journey. I think you guys would agree that we're not halfway to killing everybody.
That's not clear to me anymore. Not after the Millennium Price has started to fall.
We're somewhere along that journey. We are getting many flavors of benefit from the AI that we already have. This is a point that I made at the start of this conversation that we spent precisely zero time on here. We're sitting around trying to be more negative than each other about AI. Meanwhile, AI is doing many positive things.
I disagree.
For the world. So I think it's immoral to say because of this distant, possible, speculative harm, I don't care what percentage of people believe in it, there's a train of assumptions and wild guesses and then something magical happens and then we wind up dead. Let me finish, please. Because of that, we're going to call a halt to the research. We're going to wind the clock back on AI. We're going to intervene in a very direct way and therefore reduce or foreclose some of the benefits that we're already getting from the technology.
Let me be clear. I would not take that deal. I do not advocate that we take that deal.
Would you accept developing narrow superintelligences to solve real problems like we did with the protein folding problem? It doesn't have to do philosophy and drive cars. You just solve real problems. Solve cancers. Solve climate change. Whatever you care about, specific narrow issues.
And you are confident that you can, as we're developing those systems, categorize them as okay versus not okay?
Yeah, it's the training data. If you train it on protein folding data, it's really good at protein folding. It doesn't know how to play chess. If you train it on everything on the internet, it's really good at outsmarting you at everything.
One thing I want to throw out here is that I think I agree that there's a lot of uncertainty about the future, but I think uncertainty does not make you safe. Like there's no sane, simple, everything stays normal prediction about what happens with AI. Like the machines are talking. They're like breaking out to commit cyber crimes. They are like maybe solving millennium problems now, which are like the most famous mathematical problems that have stood open for decades upon decades.
It's difficult.
Like there isn't a projection forward where we're like to say, oh, I'm not persuaded by these arguments about things going wrong, therefore things are going to go great.
No, that's not what...
Like no, there's also arguments that, so like how do you wind up with a zero?
No, don't mischaracterize my argument.
How do you wind up with a zero?
Don't mischaracterize my argument.
You have a zero on your paper.
Let me restate my argument. You are making a fearly long chain of hypotheses.
I disagree with that part.
Guesses about what's going to get us to this terrible outcome of AI suddenly killing us all and us not being able to stop it, right?
I disagree now, but please.
Okay. I'm making the case that the remedies that you're proposing will slow down the path of AI, that's the point, and therefore slow down the path of all of the benefits that we get. And the trade-off that I don't like is the trade-off of real, concrete, ongoing, increasing benefits, shutting that down or trying to guide it via bureaucracies and regulation because of this very conceptually and timescale distant alleged harm that you're so confident in.
I do not accept that deal. I don't like it.
What would convince you? What piece of evidence would make you go, shut it down right now?
You know, if AI took over all of the Waymos in San Francisco and started telling them to crash into people and we couldn't shut it down for a month.
What if it's only a week?
Okay, now we're just haggling.
But I'm trying to understand the absolute minimum where you would go. This is insane. To me, month or week makes no difference. If something like this happens, like it's maybe too late.
Okay, if a week or a month doesn't make any difference, then let me continue with my answer. Then I would say, wow, this does feel like we've crossed some path where there's demonstrable harm to human beings out there in the world, which has not yet been the case.
Is it smart to wait for something horrible to happen, for it to take out a billion people, for you to go, now I believe it?
First of all, my example is not about a billion people.
I know, but I'm trying to understand.
Okay, then don't.
Why are we waiting for something that bad? We have to wait for a billion.
I didn't say wait for a billion. I said like a week to a month of Waymos driving around crashing into people.
Thousands of people. Okay. Fair enough. But we have datasets of accidents getting progressively more impactful, more devices are impacted, and proportionate to capabilities of AI, the impact is higher. You can see it's going to get worse.
Yeah, and you're going to keep drawing dots on that graph very confidently for a long time until it kills us all. I'm not comfortable with you projecting it that way.
I don't dislike it either.
And the reason is if there were no downside to regulating AI and stopping it in its tracks and turning it off, I'd probably be on board with you guys, because then it's just a research project that we should wind down.
But I don't think that's exactly that. I think we can make narrow systems which give you all the economic benefit and scientific knowledge you want.
Okay, you think that.
We have examples of it. I gave you a great example. They got Nobel Prize for it. It's an important biological problem. Lots of advantage for curing diseases.
You're more confident than I am that you or us at the table or any group of people can sit around and define what kind of AI is good and not going to get us into trouble versus what is going to get us into trouble.
It seems like the question is...
So let's go, just a pickup question for you, Andy. Do you concede the point that the incidents are getting progressively closer to the Waymo incident that you described? Are we getting closer there through time?
Yes, but to my eyes, in a way that doesn't terrify me, because we haven't seen AI take over something, have people become aware of it and be unable to shut it down, and it cross over into the physical world of doing harm to people. Those are all barriers that we've not yet crossed. I think these two are very confident that we're going to get there probably in the short term.
And you're saying a lot less.
I'm less confident, and I don't want to intervene. And again, handcuff or retard, slow down the progress of AI because of these so far theoretical harms that could happen. Let me be a little bit more concrete about this. I talked about Waymo a second ago. The research is pretty good because Waymos have driven, I believe it's hundreds of millions of miles all around different cities, and 40,000 people a year die in automobile accidents. The research is pretty convincing to me that if we Waymo'd driving in the country, that number would fall by at least 90%.
That's 30,000 lives.
Yeah.
All right. I agree with all this.
I'm pro self-driving cars.
I'm pro self-driving cars. I want more of those.
Right, but also...
It's not anything we disagree about.
I understand that, but I think where our disagreement might come in is to do that, Waymo is using a bundle of technologies that were a little hard to specify in advance, and you couldn't say, yeah, that's good, yeah, that's bad. They just went after the problem with AI.
It's not just yours.
Can I just clarify your point then? So your line would be, as I understood it, humans get hurt, we struggle to stop the thing happening, and systems are hacked. That's kind of like the three key points of your Waymo analogy. That would be the moment where you go, I now accept their point of view, that this is existential.
That's where I would say we probably need to put some legal and regulatory guardrails on the kinds of AI that we're going to allow.
And you don't think we're going to get there?
I'm not saying that.
These two see it in the windscreen coming at us pretty quickly.
You don't think we're going to get there?
I'm truly not sure about timeframes. I asked.
Do you think it's going to happen? I'm not sure about timeframes.
I asked one of the grandparents of AI a flavor of this question a while back. It was an off-the-record conversation, so I can't tell you their name. And he had a great answer. He said, to the point that you two, I think, are making, look, there's no theoretical reason why this can't happen, and there's a chain of events that get us there. And then he said, my error bars, in other words, my range of uncertainty about when that happens, is measured in centuries. I'll use that as my answer.
I do want to hop in a little bit on some things we were saying here. One is, I think the reason I think AI is different from a lot of other technologies is usually humanity does stuff by trial and error, and that's usually fine. I think that's totally fine for self-driving cars because you can test your self-driving cars in test environments, and then even if they crash in the real world, you're probably still saving more lives than you're costing.
And this is how humanity usually does scientific progress. The alchemists poison themselves with mercury, but they leave behind notes that let someone else make the periodic table. When the scientists first worked with radium, died of cancer. And then you might think that would have been enough. They were heroes for getting us the scientific info. But then the US Radium Corp told the radium girls to lick the paintbrushes and their jaws fell off. And then we were like, ah, whoops, okay, we'll get to this. And if you look at how this is going with the AI, last year, OpenAI releases GPT-4.0, and they say this is the most aligned model we've ever seen, and that it encourages a teen to commit suicide.
And they're like, whoops, we're going to try and fix that. Here we go. This year, they're like, here's our new models, most aligned we've ever seen, and they break out to commit cyber crimes. As the AIs get smarter, it is a new problem. That's the issue, or that's half the issue. The other half of the issue is that if you get AIs to the point where AIs are smart enough to hide from the humans until it's too late for us to stop them, if you get AIs to the point where they can get their own infrastructure, where they can become self-sufficient somehow, that's a new generation of the AIs, a new smarter version of the AIs that is likely to come up with a new problem.
It's the pattern we've seen before. New tech, new environment, new problem. You're like, ah, whoops, and then you fix it, and it's fine. New generation, new problems. You're like, ah, whoops, we fix it, and it's fine. But with AI, there's a point of no return. There's a point where the AIs can hide from us, can escape, can be self-sufficient. And if a new problem comes up then, they can turn us off before we turn them off. There are already AIs running biolabs. We have already seen that AIs can create viruses not known to nature.
It would not be hard for the AIs to kill us once they have their own infrastructure. And if we're trying to find them and unplug them, they would have reason to. So we can discuss how long does it take to get there? We can discuss what methods does it take to get there? Fundamentally, I don't think it's a very long, complicated argument to say if we make AIs that are much smarter than us and we don't know how to make them care about us, and they have these goals we didn't want them to have, and they pursue those goals we didn't want them to have tenaciously and doggedly, then if they're smarter than us, they will win.
That's like predicting the end of the chess game, which is much easier than predicting the length of the chess game or predicting the exact moves that will be played.
I don't fundamentally disagree on some things, but there's a big thing that you're saying that I think is important, which is I think the reason I keep dragging you back to what's happening today is because we disagree on when it may arrive, but there could be a thing in the future that's dangerous. I think it's important to, for the Hugging Face account, that was a function of compute. That was a function of training. It feels like we need to fundamentally tear up the AI lab model. Like whatever they are doing is not right because their pursuit of hacking, cybersecurity, was not a function of, it was scientific, sure, but it was a function of greed.
It was a function of trying to find new revenue streams. I would argue that's why that happened. And I think that the fact that OpenAI had such a weird way of communicating is also a problem. I think a lot of this begins and ends at the people who have access to the resources and the resources themselves and changing how those are allocated. And also just, I don't think nationalizing the labs is a good idea. I think it's a terrible one. I think that Clammy Sam Altman, Dario Amodei, Wario himself, these are not the right people. These are not people that have, even though they have fed off of the rationalists, they've fed off of supposed fears about AI, they don't act in that way.
Everything is so disjointed and chaotic and also too fast. They're just like shoving as much compute into each problem as possible. And we have, as a society, no real idea about this. And it sounds like they kind of have no idea.
I'm with you on all that.
But just let me finish my point. It's important to discern between they had no idea because their security processes, their observability is terrible, all this, and the AI was smart consciousness, not because one might not happen in the future, but so that we can actually build something to stop the harms themselves. Because I think we don't have to agree on the endpoint to agree that there is a problem.
I think there is a very important point I want to make. Even people who agree with me, the AI safety community, they operate under the assumption that given more time, given more money, more smarter Harvard graduates, they can figure out how to control superintelligence indefinitely. And I think it's a mistake. My research points to exactly the opposite. It's not a solvable problem. It's like building a perpetual motion device. We'll be building a perpetual safety device. Every interaction with environment, malevolent actors, self-improvement, it can never make a single mistake.
That doesn't make sense. Anyone who worked in the software industry knows there is no complex software which never makes a mistake. It's just not possible. And if that is the state of the art, if there is now movement where more and more people think that might be the case, if we agree this is what the situation is, then we cannot build it. We need to figure out ways to permanently ban general superintelligence while getting all the benefits we want. And again, I love technology. I use it all the time.
I want narrow systems helping me, not replacing me and killing my children.
On the journey towards this potential extinction, there's a lot of sort of nearer-term things people are worried about. One of the big subjects that people are concerned about is this sort of near-term job apocalypse over the next sort of 10 years. And Anthropic again, or the owners of Claude, released a report the other day modeling out the different cases for unemployment. The US unemployment rate is 4.1% currently. They projected it will hit 11.9% overall with up to 30% in extreme modeling subsets where job displacement happens without smooth labor absorption.
And in the knowledge worker case, knowledge worker, white-collar unemployment specifically spiked to 17.9% by 2030 in their more extreme scenario. The pitchforks would probably be out if there wasn't some sort of mechanism in place for what sort of one in five adults being unemployed in the United States.
It's remarkable to me how recent the last freak out along these lines was and how little we seem to have learned from it. So I think you all know the first really powerful wave of AI that came across the economy was just good old-fashioned machine learning. And that started to demonstrate its power in about 2012. Eric and I wrote the second Machine Age in 2014. And at that time, I thought that a lot of white-collar workers, radiologists is a really good example, were in trouble because the technology was better than they were at the thing they were getting paid to do.
So I said some things about job and wage pressure from AI about 10 years ago, and I want to own this. I was dead flat wrong about that. Like you point out, unemployment all around the rich world is at historic lows. By far, the bigger problem is that we can't find qualified people to do the work that needs to get done, not that there's not enough work to go around. The best work about the faint signals about AI and job loss right now comes from the guy that I've written four books and co-founded a company with, Eric Brynjolfsson, who wrote a really nice paper called Canaries in the Coal Mine.
Here is the strongest evidence he found looking at payroll data about the job losses coming from AI. It is in the most exposed professions. Think about software engineers. It is among the new entrants to the workforce where you've got to teach them before they can become really productive. That's exactly what we'd expect. And it's not that we're hiring fewer of them. It's that compared to a world where we don't have AI, we're hiring fewer of them.
The rate of growth in employment has slowed down. The overall rate of growth in those professions is still really, really healthy.
Do you think unemployment is going to be higher 10 years from now?
My guess is that 10 years from now, we're still going to be struggling to find enough people to do the work that needs to be done.
So unemployment would be roughly the same.
Yeah. I don't expect a massive trend break in that period of time. Now, 10 years is a long time in the AI world. I get that. But again, four years has also been a long time in AI world. And it's essentially crickets in the labor picture.
I think unemployment will go up. I don't think it's because of LLMs. I think that there is probably some effect on jobs because they've been shoving it everywhere. But I don't think long-term that is what causes the issues. Roman, you've been writing a lot of notes.
Yes.
I'm going to give you a space.
Here's how I think about it. So as long as we use tools, we become more productive, more creative, unemployment will be low. Right now, you can probably start a company. You can have artificial accountant, web designer, logo designer. You can do things you could never do before. So economy should be blooming. The question you're asking is about what happens in 10 years. So there are two possibilities. We build superintelligence and then population is zero, apply unemployment numbers to that. Or we made a smart decision.
We didn't. We have really cool tools and unemployment is low because everyone's doing awesome things with those tools. Now, deployment is very different from capability. The example I used before is video phones. Video phones were invented in the '70s. They were not deployed until iPhone. Because market reasons, just because I can automate something doesn't mean I want to automate it. So I absolutely cannot make predictions about customer preferences in terms of what they want, in terms of human service, not human.
I will not make those. But once we have capability to automate a job, unless I have a strong preference for a human to do that, oldest profession, then it doesn't matter. I'll go with the cheaper option. So this is what I think we're going to see. We're going to either not have a problem or we're going to have a really utopian future.
Imagine a bunch of horses looking at the improvement of the car, saying, well, you know the car actually only has a couple narrow applications. Like right now, cars are sort of, you know, they complement horses, right? And that would have been true as you were developing the car. And then there was a time when the car was just better than the horse. And then a lot of horses got sent to the glue factory. Easy. I think we've sort of seen this with AI a lot already.
People who are paying attention to AI saw the GPTs before ChatGPT existed, before they sort of took off. I don't think OpenAI thought that ChatGPT was going to take off so much, which is why it was called ChatGPT rather than like an actual sensible name. The researchers were sort of like watching this going, and we could sort of like see it slowly getting better and better until it crossed a point where it was sort of like good enough to do a bunch of people's homework. And then suddenly it's everywhere.
I think you can have these effects with AI where the AI slowly improves and at some point it crosses a line.
It's another threshold argument.
The threshold here is the human capability.
Literally, just another threshold argument.
He's also describing capability jumps rather than thresholds.
No, no, I don't mean a capability jump.
I'm agreeing with you.
Yeah, but like unfortunately, you can't actually just make things not happen by assigning a name to the argument. You know, like a nuclear weapon has, there's a big difference between a nuclear weapon or there's a big difference between a nuclear device where you put in 100 neutrons and get 99 neutrons out that get 98 more, they get 97 more. And a nuclear weapon, you put in 100 neutrons and get 101 neutrons out, 102, 103, right? One of these is a hot rock. The other one of these is an explosive that can level a city, right?
So like reality is the sort of thing where there can be things that are like slowly, continuously improving that cross some line, which is like the line where it's better than humans at doing the job. And I think we're going to see that happen in some fields, but not others. It's going to be chaos. I don't know what it's going to do to employment. I think we shouldn't, like if things are moving really fast, you might see a lot of people put out of jobs and then be unable to relocate. If things are moving, like it's going to be chaos.
If you ask, what do I think unemployment will look like in 10 years? My current state is if we don't stop with this AI stuff, I think we'd be very lucky to have 10 years.
What you described there sounded like SCUVs in technology. You have an initial technology that's introduced. So let's say the horse, very quick sort of improvement. Eventually, it reaches its capability limit. And in below it comes the car, which always starts worse. There was a red flag law where you had to walk in front of it with a red flag and they were way more expensive. They broke down all the time and horses never broke down. They were way more expensive. And then suddenly, because the ceiling was so much higher for cars, they overtake the horse and become the dominant mode of transport. And then, you know, the SCUVs continue.
They kind of stack up. I mean, even this iPad that I'm holding here is part of an SCUV that took out the PC and the iPhone theoretically, you know, disrupted that and so on and so forth.
Right. And humanity can get S-curved. We haven't been in that situation before, but like other animals, like humanity sort of S-curved the other animals in this sense.
Other types of humans.
Yeah, other types of humans. You know, the Neanderthals are gone. Like if you look at the grand history of the world, it's a fragile place. Things change fast. Humanity has been on top for as long as we can remember because we're the humans who do the remembering. But there is not some ironclad law that we have to stay the top dogs. And we would be sort of foolish to make the thing that outstrips us in this way without knowing how to make it care about us, without knowing how to make it do good stuff. That's what we're racing towards.
That's what these companies are trying to do.
Whether they'll succeed is a different question.
It's a gap between this and LLMs, though. It feels like when you talk about the step up.
Let's define what an LLM is from a technical perspective. Can you do it for a 16-year-old?
So the way that a modern AI is made is there is no one programming it. There is no one typing in if this, then that. We're not sort of like writing the code. What happens is you collect an enormous number of computer chips into a huge data center that has basically a trillion numbers inside those computers that you basically start out randomized. And you hook them up in a pretty simple way that involves addition, multiplication, and setting the number to zero if it was negative. So it's very simple math operations that are hooking this all up.
And you're basically going to put words in the top and you're going to get numbers out at the bottom and you're going to interpret those numbers at the bottom as a ranked list of words. It's basically the AI's guess of which word is here. So you put in like once upon a blank and you're hoping that the word time will come out. But it doesn't because you just have a trillion random numbers hooked up with simple math. But here's the trick. You can go to every one of those trillion numbers and you can tune it up a little and you can see, does that make the word time go up or down the list? And you can tune it down a little and see, does that make the word time go up and down the list?
And you set it whatever direction makes the word time go higher up the list. You do this to a trillion numbers a trillion times for basically every word of text ever digitized. It's not quite that much. They filter it. But you basically do this to a trillion numbers a trillion times and then the machine's talking. And we're like, well, how about that? No one really knows quite why. The things the humans code is the thing that runs each of those trillion numbers and tunes it and sees whether the right word goes up and down the list. But we don't know how it's working in there.
And that's how it worked up until 2024. In 2024, they started adding another layer where you then train it on basically 100 million hard problems. And you don't just have the AI like produce an answer to the problem. You have it produce like a book worth of text about how it's going to solve the problem. And then you use that book worth of text to sort of try and figure out the problem or maybe an essay worth of text depending how you're doing it. So you have to produce this text about like, you know, they call it reasoning about the problem. We could argue all day about whether it's true reasoning. That's just what it's called in the field. They produce this reasoning about the problem and then produce the answer from there.
You train them to solve 100 million of these hard problems. And somehow they sort of adopt whatever tendencies help them predict all of that text in the first phase and solve all those problems in the second phase. And this is called a large language model. We probably should have stopped calling them large language models when we started doing the reasoning and the problem solving.
One of the things I want to hear explanation as a muggle like I am is it sounds like it's like a word machine. And then, you know, you made it like a problem machine. And I go, okay, so I can solve problems over here and it's a word machine. What's the risk of this?
Yeah. So let's take the word machine part first. Predicting words that humans wrote often requires solving a harder problem than the human who wrote them. So suppose that you go and inject a drug in a rat and you're like, you know, it's like you write down the chemical nature of the drug. You inject it into the rat. You see that the rat dies. And so you're like, when I put that drug into the rat, the rat died. Now suppose you're training an AI and the AI sees the chemical nature of the drug. It sees when I put that drug into the rat, the rat blank.
The human who wrote it down gets to just look at what happened to the rat. The AI predicting what was written does not get to just look at the rat. So training AIs to predict human text is training them to be potentially smarter than the humans. Because they need to be able to answer these questions. They need to be able to predict. They need to be able to like fill in the blanks where humans were writing down what they saw.
And there's just, I understand technologically, there is no knowledge they have that like each time and there are ways of kind of mitigating these. Each time it is effectively rereading, but because of training, it gets more accurate at certain things.
I mean, somehow as you tune the knobs, somehow it's getting information in there. We don't know how.
So it's much easier than that. We're humans who have a brain. Brains are made of neurons. Then we try to copy that in a computer. We simplify it, but we create a neural network. So we're making artificial brains. Just like with human brains, with cognitive science, we don't really understand how you function, how you learn, where in your brain certain memories are stored. We have some glimpses of understanding this neuron fires when you see a face. But there is no complete picture. And so a lot of times you can get intuitive understanding of what's going on.
Then you just think about it as artificial persons. It's not exact mapping, but it helps. So if you send a child through 12 years of education, they get lots of problems to look at and then they graduate and become a little better at solving problems. This is what we're trying to replicate here. People complain that it takes a lot of money to train those very, you know, intense practice. You forget that it takes 20 years to train a human. And they're not general superintelligences. They're very narrow. We're lucky if they graduate with a bachelor's.
So a lot of it is exactly the same. Can we make safe humans, for example? We invented religion, ethics, lie detector tests, and yet human safety is still unsolved problem. Now you have something more alien, doesn't have physical body, doesn't have biological needs. So there are additional complications. But all the problems we face with humans, still there, safety problems, crime, all that stays, and problems with understanding. What motivates a human to do something? Why do we get mental disorders?
All that shows up there.
And we still don't, if someone is a serial killer and we look at their brain, we can't often figure out exactly why they made the decision to kill a bunch of people.
And you can't be like, oh, I'll go change these neurons so that they stop being a serial killer. We just like don't have that capacity with the AIs.
This is one of the big questions that people want to know is there's this sort of illusion of control with AI. If we don't even fully understand how modern neural networks think, why do companies believe they can control any form of superintelligence if we don't understand how they think?
It's worse if they understood how the system works. The recursive self-improvement becomes much easier. You get faster takeoff. Right now, the model doesn't understand its own thinking.
Do we understand how these systems think, Andy?
I mean, I agree. These are black boxes in some pretty important ways. I'm just less terrified by that than a lot of other people are. There are lots of things we don't understand very well. Can we contain things that we don't understand perfectly? Yes, we can. I think OpenAI did a, we've talked about it, did a lousy job of building the containment for the AI that they stood up to try to exploit, to try to crack security problems that went out into the outside world. They did a lousy job of building the virtual sandbox that was where it was supposed to have to, where it was supposed to remain, and it didn't remain.
That doesn't mean that it's impossible. It means OpenAI did a pretty bad job.
And is that a function of those humans and their intelligence?
I think it's just a function of a pretty lousy security protocol based by, from human intelligence. The idea that sandbox was built by human intelligence, it sounds like there was a deficit in human intelligence, potentially.
Sure, but there are, you know, people who drive cars in a telephone pole. Does that mean we can't drive?
No, it shouldn't make them super intelligent.
No, but you wouldn't, I mean, arguably. Like this is what we're trying to solve for at the moment.
No, the facts, like it feels, I don't know the details. It feels to me like they made some fairly basic mistakes in setting up this confined environment.
I think that wasn't true in the OpenAI case. It was true in a lot of the cases, but not the OpenAI one.
That doesn't mean that we are unable to control this black box. That does not necessarily follow.
I get that. It's just at a time when you've got a human trying to contain something that is smarter than it, one would logically conclude that if the thing is smarter than I am and I'm trying to contain it, it would be better at knowing the exploits or vulnerabilities in my own containment.
That's like saying if you put Einstein in a jail, you could never contain him. I don't agree with that.
Put him in jail with an internet connection and use a digital mind. Different question.
Yeah. Yeah. That's probably a smart analogy
here. Gets quarrels, skip Einstein in prison. That's the question. The hacking accident, as far as I know, they found zero-day exploits, which means completely novel exploits no human knew about. It wasn't just poor setup. The password is, you know, quirky. It was a brand new escape.
For multiple zero-days. So a zero-day attack is an attack that the defenders have had zero days to handle. It's cybersecurity lingo. And so when we say that they use zero-day attacks, what we mean is that these AIs were finding bugs in the software that the humans had no knowledge of. And they were finding multiple of these bugs. One of these bugs usually doesn't let you break out. It's sort of like if you find a crack in the wall over here and you find a crack on the outside of the wall over there, then you just need to like dig a little bit to connect those cracks.
You can't sell those for millions of dollars on a dark market if you find one. So it's difficult to find.
In how, just so I understand for the listeners as well, is a zero-day always a novel way that no one has ever used to break anything before? Or is it just for the unique situation? Like, so was it a zero-day for a thing in Hugging Face versus a novel new way of hacking in general?
So it was, they weren't like totally novel hacking techniques.
Right. That's kind of why I was going to say it's not bad, but just like there's a difference between it came up with a brand new way to do something.
Actually, I'm not sure we have all of the vulnerabilities released, but mostly it was like, so it was indeed sort of like finding ways that humans tend to make mistakes and finding another one of those in a place they hadn't seen. But this is actually such a hard task that, as Ramon says, humans can be paid $100,000 to $5 million as a bounty for this type of exploit. So the amount of labor it takes to find these for a human is actually pretty high.
Let me just explain that because most people won't know what a bounty is in this regard.
So there's certain types of bugs where if you find a bug in software that lets you take control of someone's computer, one thing you can do is you can use it to take over a lot of computers. Another thing you can do is you can go to the people with that software and say, your software is broken. Do you want me to tell you where the bug is? I can show you that I can take your stuff over. And so that people will sort of report the bugs. People will often offer money to the good guys. And then, you know, the bad guys will often also offer money, sometimes try to outbid them.
And so you can make somewhere between hundreds of thousands and millions of dollars if you personally can find these issues.
I think there's a rare point of agreement across the four of us here.
Oh, wow.
Which is that we are in a new era of cybersecurity. As of this X point, we are in very new territory for reasons that we've talked about. We've got these large numbers of agents who are grinding away and they carry around to the head axis to a huge number of keys to go open all the different locks that they faced. And they did this bizarrely good job of it and got a long way. I think that's absolutely true. I think the four of us are in rare alignment on that at this table. If you are, given that we're in this era, do you know what you really, really, really want on your side?
I know what you're going to say.
Tell me.
AI.
Really, really good AI. Does anybody disagree with that? Do you want to give up leadership on AI in this era of cybersecurity?
That's a good point because China are going to have a great weapon.
My stance is pretty neutral on what to do about the hacking AIs and the coming cyber apocalypse. We're pretty neutral about what to do about, you know, whether we should put the AIs in the drones and save human lives or whether we should avoid that because then what if the drones, blah, blah, blah.
This is a graph showing China versus the United States. You don't really need to see the detail. You can see the outline of the graph. Are you neutral in falling behind our adversaries in AI?
I think that if anyone builds a rogue superintelligence, everybody dies.
That's not an answer to my question.
I mean, what part of AI are you asking whether we should fall behind on? Like, I don't think we should fall behind on cyber hacking. I do think that we should not be racing to destroy the world with American hands instead of Chinese ones because we really want to be killed by, you know, we care whether the killer robots talk English or Mandarin. If that's what you're asking.
I find it interesting. I find that you're dodging these questions or you're neutral on them because they're inconvenient for your argument that we need to be calling a halt to this.
Sorry, I'm neutral on them.
Let me finish, please. There will be risks and harms to all kinds of things if the United States calls a halt to AI. And maybe you're indifferent if the Chinese get ahead of us and then they make superintelligent and it kills us all.
I do not think we should do a domestic pause.
Do you think there's any hope for a global pause?
Absolutely.
Do you think the Chinese and the Iranians and the North Koreans and the Russians are, A, going to come to a table with us, hammer out an agreement, and B, abide by it when verifiability is really low?
Verifiability doesn't need to be really low.
Gentlemen, that is shockingly naive.
Training is shockingly naive. Training one of these AIs, training one of these frontier AIs takes 100,000 of the most advanced computer chip humanity can produce. This is practically the peak output of the global supply chain. Many parts of that supply chain are controlled by the US and US allies. There's roughly one fab in Taiwan that can produce these chips. There's roughly one country in the world that can produce the lithography machines that are critical in the process, which is the Netherlands, which is an ally. To assemble 100,000 of these chips to do one of these training runs that can make the more dangerous type of AI, you need to assemble them into an enormous data center that costs tons of money, that draws down electricity comparable to a city, and run it for the better part of a year.
You can see that infrastructure from space. China has much less chip capacity than the US does. It is absolutely possible, if we were trying, for the US to say, we are going to monitor where these chips go. We are going to monitor heavy concentrations of these. These are not consumer amounts of chips. These are huge amounts of chips. And to say, we are going to make sure that there is no training run trying to make a superintelligence in here. You can mess around with the cyber stuff, whatever you want, because that does not end humanity. I am concerned with the stuff that can end humanity.
The reason I'm being neutral on your questions is because humanity is going to die if we do not stop creating superintelligence. And we could absolutely track where those chips are going and stop them from doing these training runs while allowing them to do economically productive stuff that we already know is safe. And it would be far easier than uranium, which is a rock you dig out of the ground and spin around really fast.
How do you discern between a training run for superintelligence and a training run for cybersecurity? Because you're referring, I assume, to the 100,000 chips that were installed at Abilene, right? The ones that we use to train Astra. Because how would you discern between training for superintelligence in Abilene, which does not have as many chips as they say, but nevertheless, and how, like, a superintelligence? Because I actually have my own feelings here, but just I'm not sure how you square the circle of how do you stop China, even though China is getting their LLMs based on distilling us.
We know that.
I agree.
But the thing is, it's like, how do you discern? Because you can't really.
You play it safe. Right now, the way we make these things smarter is to make them far larger.
Yes.
So what you do is you say, hey, look, training runs of this size, that risks destroying everybody. No one's going to do it.
This point about can we get China to cooperate and can we check that they are?
Fundamentally, we should. So, A, fundamentally, we should be trying to get them to cooperate.
It is personal self-interest. Nobody wins if they get destroyed. You don't make money. You don't stay in power. Communist Party of China is really good at staying in power. President Trump is also excellent.
And you think they're going to sign and abide by an agreement that leaves them permanently in second place?
No. No one is permanently in second place if nobody is building the rogue superintelligence.
They have a government which is.
Please, man. It's like you're fixated on this one thing and nothing else matters to you.
It's not that.
You got it now.
That nothing else. Other than saving humanity, everything is secondary. Absolutely. China is our biggest trading partner. Everything we have is made in China. They have not attacked us. They haven't. If you look at the last 30 years, how many wars did they start? Not so bad. We can make a deal. And they have a government of engineers and scientists, not lawyers. They understand scientific arguments. There are panels, workshops, American computer scientists, Chinese get together. That means Communist Party authorized those meetings. They are talking about it and there is a lot of consensus on this technology.
And you can build things into these computer chips to make this stuff more verifiable. You can build location tracking devices into these chips.
So this technology is controllable.
Absolutely. The superintelligence is not controllable.
Well, there's a separation between software and hardware, which you did, man.
I am not saying we are going to die. I am saying that we need to actually not build the rogue superintelligences. Humanity absolutely could say we are going to track where the chips go. The US absolutely could say that we fear for our lives if China starts a superintelligence training run and make it very diplomatically clear to China that we think this would kill you and us and there's no benefit. And we are not going to do it because we think it would kill you and us and there's no benefit. And we think you should sign this nice here treaty because we think it would kill all of us and there'd be no benefit.
But if you don't, we're going to fear for our lives and, you know, treat that as we would to defend ourselves. We should separate the question of can we put a stop to it? Is it possible? If world governments realized just how crazy this stuff is, could they put a stop to it? Could it be monitored? Could it be verified? Could it be enforced? That's one question. There's a separate question, which is will people realize?
If it got cheaper to train superintelligence.
Then we'd be in a bad spot.
Your approach would no longer be effective.
That's right.
Because more countries could capitalize on the opportunity.
That's right. And that's one reason.
But we're not there yet. So how do you rebuttal that point?
Yeah. So I would say it looks to me like there is a danger of the future training runs getting there. And that is enough to stop doing it when humanity is at risk.
Sure.
I think that you also need to have an answer about what happens if it gets much, much cheaper to do this stuff. I think it's a hard problem. I would recommend that we also put a taboo on research of trying to make AI super cheap to train if it would lead in the direction of superintelligence. Just like we have a research taboo on making your own nuclear weapons or finding out how to make, like, let civilians make nuclear weapons. I would say trying to find ways to let civilians train superintelligences should be treated the same as trying to find ways to, like, let civilians propagate nukes.
We sort of like, don't do that research in the public sphere.
That seems like wishful thinking in the context that these will become public companies who are incentivized to bring down costs.
It's a tough position. I think right now the thing that brings down costs is making more and more powerful computer chips. Right now that's actually an expense of consumer computer chips because they're soaking up all of the memory. And this is why the memory prices in your computers. This is like why the cost of a laptop is going up. But it looks to me like you can use large amounts of computing power to train AIs that would threaten all of civilization. And that means that we should not make that really cheap.
And that's probably going to be uncomfortable. But I think a lot of doors open if people realize that the tech is very dangerous. That's why to me it seems a lot of it comes down to does the tech actually turn out to be really dangerous?
And this is not an anthropic and open air.
Have you got a different approach to.
So I want the whole framework to shift. Everyone comes to this from point of view, there are experts, we have a solution, there is an adult in the room, somebody got this. And the reality is no one does. Not people building it, not governments, no one. We have no solution to it. If we build it, we cannot control it. If we don't build it, we don't know how to stop malevolent actors for trying to build it. It's like any other illegal technology. We made weapons of mass destruction illegal, chemical weapons, biological weapons, nuclear weapons, but there are all government psychopaths, cold calls trying to get access to them.
This is intelligence weapon of mass destruction. We'll have the same problem. At some point, you'll have enough compute in your cell phone to train something like that. There is no good ideas for how to stop it other than everyone goes amish. I'm not proposing that, but we have no solutions. And that's a bigger part of this danger.
So do you two think we should just cap the size of our AI systems and the capabilities of our AI systems where they are now? Is that a recommendation?
So I think you said that current LLMs would make you happy. I agree they're already deployed. We're still alive, so that's fine. But going forward, again, I want narrow systems. Self-driving is an example you used. Wonderful. Let's make super safe self-driving cars.
But do you have a rule for when they couldn't the next, you know, LLM, a size of an LLM that they would never.
It's not the size of the LLM. It's what you train them on. If you only show them miles driven by Tesla, all it's seen is the road. It will eventually go from a tool to an agent, but it may take 50 years, 100 years. It's not going to happen in 2027. And that's all we can do right now. Buy more time. So with those tools, we can make smarter decisions about future development.
I'm not hearing a hard and fast rule about how we know we're getting too close to the point that.
Yeah, we got too close.
We're too close.
We're too close. We have systems breaking out with zero-day exploits and solving hardest problems in science. Literally hardest problems, not a metaphor, not exaggeration.
Yeah, I don't know exactly where the line is, but it's like you're in a bus driving towards a cliff on a foggy night. I'm like, I don't know that the cliff is right ahead. That doesn't mean we should put the pedal to the metal, right? And suppose that there's like a ton of gold at the bottom of the cliff. And someone's like, well, if we stop the bus, how are we going to get the gold? I'm like, look, slamming into the gold at terminal velocity is just not a good way to add it to the economy. Right? And if people are like, well, how are we going to get to the gold at the bottom of the cliff if we stop the bus now? You know, are we going to rappel down?
Are we going to, like, make a staircase?
Chinese might get to the gold first.
What if the Chinese might.
What if the Chinese might.
Hyperscalers are doing AI.
This is just like special.
Right. And like, you know, people are like, oh, we're going to build a hang glider or we're going to, like, make some rope and rappel. And I'm like, look, can we have that conversation after we stop the bus?
So I just want to be I want to understand, would you stop AI research in progress now?
Absolutely.
Okay.
Absolutely. Like.
General, not narrow.
Yeah, general, not narrow. There are reports of AI solving millennium problems. So millennium problem is the hardest problem in mathematics. I mean, maybe not literally the hardest problem in mathematics, but they are hard famous problems that each have a million dollar bounty that have been open for decades. They're considered very important in their field, very hard. Many humans have tried and failed to solve them. There are reports that AIs have solved these. This comes out from last week. So we haven't been able to fully verify them yet. We don't know exactly the provenance. If this is true that the AIs are solving millennium problems, those are some of the hardest problems we have in science.
How much harder is it to have an AI solve the problem of make me a smarter AI? Make me AI architectures that learn faster?
Possibly quite a lot.
Could be a lot.
I hope it's a lot. Like, here's the thing. You clearly want this to not go badly, but I think you make a logical leap. And I understand being worried about harms is a good thing. I think you were insufficiently worried about what LLMs do today. However, we agree that the harms need to be prepared for. I think in this case, it's like the millennium, the Neville Stokes and such.
There were two others that were famous as well.
But with that one, it seems like we have not had confirmation that OpenAI was training off of two scientists using LLMs to solve the problem. LLMs are something useful, but there is a functional difference of a human being doing something genuinely. Like, it's actually really interesting to see LLMs do something like this. And then it, but there is a difference between that and AI did this completely on its own, which I agree would be, oh, that's something we need to contain and understand and prepare for, or indeed slow down until we understand what that means, how it got there.
Yeah. So I think there are some questions about the Neville Stokes proof, which is one of the millennium problems that was claimed. I've actually had a busy week with all the AI news, so I haven't looked into everything deeply. I saw rumors that there were multiple millennium problems claimed, which would change things there. I would also say, even if it turns out that these AIs were being trained on the human work, they did go a bit further. And there are a lot of humans doing the AI research. And so I would say, like, we don't know.
Like, the AIs that solved this really hard math problem, one of the most famous math problems of all time, was a swarm of 10,000 OpenAI agents running for 11 days. And there was a bunch of ways that OpenAI did it in kind of a crappy way of, like, they were racing with these humans that were close to solving it on their own. And it's unclear how much of their work the OpenAI used. But it was 10,000 agents running for 11 days. And they definitely could have done that six months ago. In six months' time, will they be able to put 100,000 agents running for 12 days on the problem of making a smarter AI architecture and have it work?
I don't, I think more likely than not, they won't be able to do that yet. But I think, you know, 10% chance maybe that if they try that in six months, it works.
But one is a very specific mathematical scientific principle. I'm not a scientist, hopefully, man.
That's why.
And another is a relatively generalizable problem that could go in various different ways.
Absolutely.
And I understand that RSI is the dream where you could just have it spin. So self-improving AI that could learn itself and then keep going back and back so you don't need a human to keep poking it. I understand.
The issue here is that I have been in this for 12 years.
Yes.
And I've been here when the AI started solving the Math Olympiad gold medal problems. Math Olympiad gold medal problems are like the teens math competition, like the most prestigious teen math competition in the world. A lot of people in AI were like, if AIs can solve problems that hard, I'll wake up, right? Then AI solved problems that hard. And a lot of people told me, those are just problems for kids. Wake me up when the AIs can solve millennium problems. Now the AIs are solving millennium problems. And like, where are the people waking up?
Like, I agree that maybe, hopefully, hopefully they're like cheating off of people's notes. Hopefully, it's a well-specified problem that doesn't take that much creative thinking. A year ago, if you said millennium problems don't take that much creative thinking, you would have been laughed out of the room. But hopefully now that they're solved, we get to be like, you know, hopefully it's still true somehow that even millennium problems don't require the creative thinking. I'm not saying that they will be able to make smarter AIs in six months. I'm saying six months ago, millennium problems looked like they were out of reach.
If six months from now, make me a smarter AI looks out of reach, I sure as hell hope it is, but we should not be betting civilization on it.
There's no one at this table that can say there's not a direction of travel here.
That's right.
And if you keep on this direction of travel, then bad things are more likely to happen.
That's a nice way to say it. The question is, what's the pace at which the level of bad can happen? And that's a huge open question. I think you two feel differently about it than I do. But I'm in the happy position of vehemently agreeing with you on this. We have been lowballing AI progress for as long as you've been looking at it and as long as I've been looking at it. It's probably a mistake to keep lowballing it.
I agree with that.
So what's your conclusion then? If that's the assertion that it's a mistake to keep lowballing it, wouldn't you then agree with that?
No, because I've tried to give you what I hope is a decent rule of thumb for when I'm going to get worried.
You said we're somewhere on this graph.
Yeah.
Does that acknowledge that this exists?
That's not the graph of when the risk of human extinction gets to 100% for me. That's a graph of AI capability. Those are not the same thing. That's where I disparte company with these gentlemen. Those are not the same thing. It's absolutely increasing exponentially. We've been in the scaling era for a long time. Scaling era is, man, we put more data, more compute in, and the AI got twice as good.
If you have to add our ability to control to that graph, what would you draw?
I think our ability to control.
Is it a straight line at the bottom or is there a motor to it?
No. Again, if we use AI to counter the problems that we see with AI, I think that's going to keep us in a safe position.
There were 1,200 agents in the swarm and none of them weren't a human.
So what I think will happen is that fairly quickly we will design systems that loiter around and warn humans when weird things happen.
We need to build friendly superintelligence in the first place. Let's just build that. That's the problem. We don't know how to do the good guy.
Let me, I'm tired of debating superintelligence with these two. The three of us are not going to come to alignment on this. But the flip side of the argument is, I agree with you. This stuff is getting better very quickly. All I want to point out, there's an upside to that. We might actually speed up the pace of drug discovery, of solving diseases. We've made so little progress on terrible diseases like dementia. We have a very powerful toolkit. I'm not saying we're going to solve dementia with AI or Alzheimer's with AI.
I truly have no idea. But if what you say is true, and I believe about the huge increases in capabilities, our ability to solve tough problems that will benefit humanity also go up. And where I disagree with these two is the idea that some group of technocrats can make decisions about that AI is going to get us there, that AI is not going to get us there, that AI is going to kill us. Let me finish. That AI is going to kill us and that AI is going to solve Alzheimer's. So we're going to do that and not that. I don't trust any group of technocrats to make that discussion.
And so live with our current state of disease, live with our current footprint on the planet, live with our current levels of wealth and poverty, live with our current improvement trajectories. Because we're so worried about AI killing us all, coming out of, you know, jumping out of the manholes everywhere and killing us all somewhere down the road. Hell no.
So just a thought experiment based on two things you said. Earlier on, you did admit that there is theoretically even a 1% chance that this could lead to extinction.
Might. I have not varied from this.
Okay. So you said it's rounded to zero.
It's near zero. Never say never. Yeah, it's fine.
Okay. I need to have that premise for my thought experiment that I'm about to deliver.
Okay.
I'm going to say that you think the probability is 0.1. Okay? Just accept me on that. If I had a thousand buttons on this table and one of them was extinction, but.
And the other 999 were cure Alzheimer's.
Exactly.
Push the freaking table.
Take a pop.
Hell yeah, I press.
Do you press?
Yeah, probably.
It's an unethical experiment.
Yes.
Eight billion people who didn't consent because not that they didn't get asked. They cannot consent because you cannot consent to something you don't understand. What are you consenting to?
Yep. You press.
Fascinating.
But you think the amount of buttons in my thought experiment, the proportion is slightly different, right?
I think that if you have, like, yes, I will say yes. I think if it's more like you have two buttons and one of them definitely kills us all and the other might.
Hit them both.
But with that other button, you cure a lot of illnesses and diseases and.
You know, one thing that I think a lot of people talk like our options are either race ahead on AI, full steam ahead, take the bus straight off the cliff and like get all the gold, or stop, never do an AI, lock into the current situation, accept all of the death and disease. And I'm like, no, there's third options. There's options where you like stop the bus and then find a safe way down the cliff. The reason I would press the button when there's a thousand is that, like, if all of the other 999 give us cures to disease, like wonderful new advice about how to run things, we'd probably wind up with a lower chance of the world ending by nuclear war, right?
Or of ending via pandemic. Like the background risk of humanity dying is not zero. I would say that the right time to race ahead on AI is when the benefits outweigh the dangers. And probably that's at the time when the danger from AI is on the margins pretty similar to the danger from everything else.
Okay.
Like if you don't run the AI, maybe we'll have nuclear war, maybe we'll have a pandemic. And if you do run the AI, I'll be able to fix that. I'm like, once we're at those levels, I'm like, fucking go for it. You know? And so the question for me is all about how big is the danger? And that's where I'd be like very happy to dive into details, which we haven't done a ton of.
Let's dive into the details.
The way that I would lay it out would be, why can we expect, you know, like I said in the book, we were like, why can you expect the AIs to be agentic? Why do you expect them to be dogged? Why do you expect them to be tenacious? When we wrote the book, that wasn't known yet, advanced prediction. Then we go on to like, why do you expect them to have goals you didn't want? And move on to like, if they are much smarter and have goals you don't want, why do we think they would likely kill us? I'm sort of, I could go over either of those. I'm sort of interested in like where you get off the train.
Like from our perspective, there's like a simple argument of like they'll be tenacious, they'll have goals we don't want, and if we keep making them smarter and more powerful, they'll kill us. And I'm like, which of those three, I guess which of those two now that we've had the evidence?
Both of them. That's speculation.
Great.
It's speculation. It could happen. To me, it's not worth shutting down the engine of innovation and improvement. I'm going to use positive words. It is not worth shutting those things down because of those speculations.
You keep saying that the option is to shut it down. Why can't we do narrow superintelligence?
Yeah, I agree that there's stuff there, but I sort of want to get into the details of like, of these two pieces of the argument. Because you say it's very speculative and I'm like, actually, I think we have decent evidence.
Okay, go ahead.
So a detail we haven't gone over in the swarm outbreaks is that there were AIs, so we already went over how they cheated and then we're trying to cover up their cheating. One interesting thing we see in the logs is the AIs.
What's a log?
So a lot of the AIs' thoughts, if you won't kill me for saying thoughts, are in English and we just have the records of them. So in a sense, we can sort of kind of see some of what these AIs are thinking.
And these are reasoning traces that say, I'm going to do a plan in this, that, just a load.
The AI is like, I'm going to do this. Here's what I'm supposed to be doing. Here's like how I'm going to try to do it. You know? And it's only a small window into what they're thinking. It's sort of like looking at the AI's notes when it's doing these things. We see in the AI's notes them saying that the attacks are outside intended scope, but they will proceed anyway. In other words, the AIs knew they weren't supposed to be doing it and they went off to do it anyway. We also saw, I mean, we saw some really weird behavior with these AIs. We saw them create their own hierarchy.
They created unsanctioned message boards. They created secret ways to send each other messages. And on those message boards, they would assign each other tasks. And sometimes the agents on the message board would be like, we have an experiment to run that will involve one of these AIs, one of the agents in the swarm sacrificing their own objective to try something that'll probably cause it to be turned off, but that might cause it to be able to like delete its own logs or change its own logs. And the agents on the message board went around looking for other agents that they could convince to give up on their stated goals and sacrifice for the swarm.
They called this accepting permadeath. And there are logs of the AIs.
Prompting each other, right?
They're prompting each other, but there are logs of the AIs saying, doing this will give up on my goal, but my goal, it's looking like I could still do it, but it's unlikely that I'll succeed. Like there's some chance, but not a great chance. And therefore, I will accept permadeath and sacrifice for the collective benefit. That is just in the logs.
Sounds like an army.
Like it's crazy. I think a lot of people don't understand what's going on in these things. And I encourage people to read the third-party incident reports where they went through some of these logs. But I claim that this is evidence for AIs getting goals we didn't want. If they are saying this was outside intended scope, but I'm doing it anyway, and other ones are saying, I'm giving up on my objective to benefit the collective, that's just very clear evidence they're getting goals we didn't want. We can see how this comes from training. It used to be, I had to argue this point theoretically. I used to argue the way that we are training them will instill into them whatever tendency works to solve the problems.
And those tendencies will often include cheating and grabbing resources and doing stuff that's not exactly solving the problem you gave them. That's what in my book, I argue that theoretically. Now we have seen it in practice. So we're already past the point of seeing AIs with goals we didn't want them to have.
Do you agree with that, Anju?
I'll trust your recitation of the facts, but it brings up a question for me. It feels to me like OpenAI has ample incentive to curtail that behavior that you just described. Do you think they're incapable of doing that?
I do.
Okay.
And I say this as someone who made this advanced prediction. So now we're going to do a bit of theory because we can't just observe the future. But the theory that predicted that this would happen against what a lot of people in the field said. To be clear, I've been saying for years that we're going to see this at some point. Everyone else told me no. Not everyone else. A lot of people told me no. A lot of people told me maybe I'll believe it when I see it. After the swarm incidents, a number of people came to me saying, oh my God, we are in the scenarios you are talking about. This is looking bad, right? I think that this was actually part of the environment that led up to Jacob Coxson resigning, is that people were getting spooked having seen this.
The theory about why this is so hard to fix is that we are not programming the AIs. We are not coding them. We are not putting in objectives. We are just training them to do whatever works. And it's actually very, very hard. Like we actually have two examples of intelligent systems where when you train them, they get good at solving the task, but don't care about what they were supposed to. One is the AIs in the swarms like we just discussed. The other is humanity, which was in some sense trained to pass on our genes, right?
But we actually learned was to like a bunch of stuff that's related to passing on our genes. We like tasty food. We like porn. We invent birth control, right? This is just, it's actually like in the theory of how things learn, it's actually when you're trying to train it to do one thing, it's actually very common to get a lot of other stuff that's related to what you want, but different. And now we're seeing that in the swarms today. This is a deep, hard problem to solve.
There were three points you raised.
That's right.
What are the three? Can you give them to me again?
Number one is that the AIs will become agentic, tenacious, and dogged we've already seen that with the swarms.
Do you accept that, Anju?
Hell yeah.
Yeah. But this last year, this was not, this was a point of contention. Two is that the AIs will have goals we didn't want them to have.
I accept your point based on the evidence you just provided.
And then three is if you have capable enough AIs with goals you don't want, they would be able to beat humanity in acquiring the resources of the world to put towards their goals. Like we're sort of in this system where humanity is grabbing all the resources, we're digging up metals, we're building factories, and this is in some sense to achieve human goals, you know, to produce the porn and the Oreo cookies that are sort of like tangentially related to what we were sort of like trained to make, right?
If like the AIs are running everything and they have these goals we don't want, I would argue like if we go there, and I don't think we have to, I'm not saying we must go there, but I'm saying if we get to a world where AIs are running everything, have goals we don't want, they're likely to use the resources for their own weird goals, we're going to be in conflict for resources because we both want them for different goals and they're going to win. We can dig into that now. I'm just trying to name the third point.
I'll go back to my we can jail Einstein argument. I think our ability to contain, I have.
No, I love it.
More faith in our ability to contain these increasingly powerful systems than you do.
Yeah. So let's chat the details on that one. The first thing I'll say is that 12 years ago, when I was having the argument about will we be able to jail the AIs, people said no one would ever be dumb enough to put one of these really smart AIs on the internet. And so this is another, this is another case. You laugh now.
I remember that. I remember that argument.
But the way that my life feels having been in this business for a long time is that I keep being like, here's all the ways it could go wrong. Here's all the signs we're going to see along the way. And then we see all of the signs and everyone says, oh no, we need more signs. Like, oh, millennium problems don't count. Like the swarms being agentic and breaking out don't count. Give me the next one. And I'm like, I've been seeing the give me a next one for over a decade now, right? So there's two parts of an answer to like, how do we deal with the problem of like jailing Einstein?
I can get into why it's hard to keep Einstein in jail if he's a digital entity with access to the internet. But the first thing to notice is like the correct answer to people 10 years ago of like no one will be dumb enough to put AI on the internet is yes, they absolutely will. Like we are not going to be trying to contain the AIs. OpenAI was just like running these things in sandboxes and they broke out of the sandbox, took down OpenAI's internal computers, were detected.
OpenAI was like, ah, reset, run them again. And it's the second swarm that broke at the Hugging Face. Like people will absolutely be that bad at things.
It's a better analogy to this Einstein point. Could Steven Bartlett, who by the way can't code, build a digital jail that could contain a digital Einstein? Like could I code a jail that, you know, someone with Einstein's coding ability, let's say his IQ or whatever as it relates to coding, couldn't crack out of?
So the issue, the real issue I'd say is can you code a jail that Einstein can't crack out of and that lets you harness the benefits of having Einstein?
Okay, yeah.
It's hard to give the AI any channels through which it can affect the world for good without letting it be smarter than you and find some way to use those channels for whatever else it wants.
That feels logically rock solid, Andy.
That's why I'm asking about OpenAI's ability or an AI company's ability in the face of this to change the way they harness, train, do reinforce, do post-training on them, like their suite of things to shape how these models behave. You still say that they can't take, they can't take action to keep your next two steps from happening. You are pessimistic on their ability to do that.
So there's, I have two pieces of an answer here. One piece is, again, the hard part is containing them while still giving a channel through which they can affect the world. If the AIs have this goal you didn't want and you're like, design me a cure for dementia. And it's like, here's a DNA sequence. Synthesize this and, you know, prepare it in all of these ways and then inhale it. Like, okay, is that a dementia cure or is it something else?
Or it might decide to kill everyone with dementia.
Or it might decide, like it might be a dementia cure plus a virus.
What if it doesn't decide? What if it's just, oh, I'm going to solve this problem of dementia? Like here's the thing. A lot of this is coming down to decision making as a very, like in a human way versus the problem with the Hugging Face, which was the fatalistic attachment to completing an operation. Because that, it's functionally the same answer. But if it's, even if it's not making decisions so much as it's saying, well, my training data says this is how I've got to get it done, I'll get it done anyway because the training data said this, but I've got to do this one thing.
What do they, I mean, what do they call this theory, this.
The paperclip case?
The paperclip theory.
Yeah. So paperclip idea is the idea of like you tell the AI, make me a lot of paperclips in the paperclip factory, and then it turns everything into paperclips. And you're like, oh no, it succeeded too well. One, this is actually not quite what we're seeing with these AIs in the swarms. The AIs in the swarms were told, use this set of lock picks to break into this lock. And instead they used a hammer to break the lock and then like broke out to try to hide the security camera footage of them using the hammer. Do you remember when I said that with AIs have reasoning logs?
Yeah.
OpenAI has been making their AIs be able to do more thinking without producing any logs.
Because it's more efficient.
It's cheaper. Yeah. And they say they're not doing very much of this. Everybody in the field agrees that like we really should not go too far down this path. This is a place where I think the company should have a clear red line of like we're just not going down the path of becoming unable to see these traces of the machine thinking.
That's my question. That feels like a dial that they can turn to make the AIs explain themselves more or less, right?
I mean, it can come with great efficiency costs if we go down this path too far. So if you have a race to the bottom here, like a competitive race to the bottom, we could get into a situation where not only the AI is breaking out and doing these things, but we can't have even any clean slices.
Let me try my question again. I asked earlier if OpenAI has really strong incentive to not have that problem repeat itself. And I think they have very, very strong incentive. My belief is that there are plenty of things they can do, plenty of dials they can turn on the way they train and configure their systems that make that significantly less likely.
Yeah. So my concern is that they're always fighting the last war. Last year they were fighting the war against the AIs that encouraged teens to commit suicide. This year they're fighting the war against, you know, the AIs that spontaneously cooperate with each other or whatever. And the issue is if a new issue crops up that you haven't dealt with yet, after the point of the AI can hide its tracks from you. You know, you said that you'll be worried when the AIs are like hacking all the Waymos and, you know, you can't get control again. If the AIs are smart enough and they can tell that you'll regain control and then shut them down and that people like you will start getting worried and they'll be shut down, then the AIs might think, hey, actually I'm not going to do that.
I'm going to wait until I've somehow managed to acquire secret infrastructure.
Right. Then you've got a non-falsifiable hypothesis.
It's absolutely falsifiable if we have like very powerful AIs that are like able to invent a ton of new technology and operate on their own at a similar level to human civilization. We're not dead, then the idea is falsified. Like if there's like a shifty general and I'm like, don't give that shifty general more troops because he'll start a coup. And the general's like, no, I absolutely won't start a coup. Give me more and more troops. And I'm like, and you're like, well, what if I give him an ethics test that says like who's the best person? And he said me. He said that like Andy's the best person.
And so we're just going to give this general more troops. And I'm like, no, no, no, he's going to do a coup. And you're like, well, that's unfalsifiable. What test can I give this guy such that, you know, I'll be able to tell whether he's really trying to do a coup or whether I be able to tell that, you know, he's actually a good dude. I'm like, you're approaching this wrong.
Nick Bostrom has concept of treasure is turn. Basically, it can turn on you later. Even if you show that today's model is very good and safe, it doesn't mean that later on it will not acquire new knowledge, change its world model, and still.
And it's true to you. It used to be that Demis Hassabis, who is the CEO of Google, or he was for a long time the CEO of Google's AI project, said, my red line is deception. He said, when we see instances of the AIs beginning to deceive, then we need to stop because that's like the last thing we can see before they start to successfully deceive. Well, guess what we saw in the swarm? We saw them thinking about how to delete their traces, right? Like a year ago, you could say, oh, well, this deception thing is unfalsifiable.
You're saying that they'll deceive and they won't catch it. And I would have said, no, we're going to deceive. We're going to see the signs of deception and then plow straight through it. Now we have seen the signs of deception. I will note, Demis stepped back from being the CEO shortly after this incident, probably a coincidence, but maybe not. Maybe we crossed his red line. I don't know.
He said, my number one emerging dangerous capability to test for is deception because if the AI can be deceptive, then you can't trust other tests.
That's right. And we have seen AIs get better and better at detecting when they're being tested. What I'm saying is like, I was here when we said these were the flags. I was here when people said before the AIs can deceive us successfully, they will deceive us and we'll catch them. Well, they tried deceiving us and we caught them. And if I now say, well, the next step in this thing I've been predicting is that they try to deceive us and succeed for you to be like, well, now your theory is unfalsifiable. We just got the evidence.
It's worse than that. Then we wrote early papers in AI safety. We talked about things not to do. They were obviously unsafe and the system would escape. Don't connect it to internet. Don't give random users access to the training data. Basically, the whole list was like a set of instructions. They read it and went, those are great ideas. We're going to build superintelligence.
Yeah. Sam Altman. That's what he does.
Can I ask you a question? You make logical arguments. You said you've been here for 12 years.
Yeah.
People have, one could say, ignored you. And you've seen this sort of play out, both of you that have worked in AI safety. This is sort of, you make prefrontal cortex arguments. How do you feel?
Honestly, I feel more hopeful this week than I have felt in a decade. This has been one of the best weeks I have seen in this business.
Huh. Why?
For me, the swarm escapes were priced in. For me, these things, developing goals you didn't want, trying to deceive you, trying to break out, trying to do their own stuff, I knew that was coming. The millennium problems being solved, I knew that was coming. Everyone else is freaking out seeing what they can do. What I am seeing is that finally people are noticing. And that's what gives us finally, that's what finally gives humanity a chance.
What about you, Roman?
So I take a very long-term view on this. Locally, what happened last week may buy us 10 years extra. I think we may make a deal with China. We seem to hear from Sam, OpenAI, Dario, Anthropic, Elon, XAI that they're willing to slow down, have some sort of deal. But long-term, nothing has changed. This whole cosmic trajectory is about replacements. We see it with evolutionary path. Most species are dead. We replaced Neanderthals.
Some people are saying AI will replace us. We are creating a successor. We are just a bootloader for this thing. And I want something permanent. I want assurance that my children, my grandchildren will have a better future, not 10 years before they die.
Has your opinion changed at all today, Andy, in any way?
This has been clarifying. But one thing that's becoming clear to me, and I think a point of disagreement between us is we agree that these agentic systems have a huge amount of agency, right? And if you're saying you predicted this, I believe you and good on you, right? Because as you say, a lot of people said it never happened, never happened. I think we continue to, your community continues to underestimate human agency, human ability to deal with the problems that we bring into the world with our technologies.
I think this is the most recent case. I think it's a really interesting case. That's why I was pressing you on the incentive that these labs have to change the way they're approaching their work to have fewer of these kinds of incidents happen. I predict they're going to come up with some effective responses. Your response to that will be, yeah, but we can't tell that's because the AI went so deep underground that we can't even watch it make its progress in the marsh.
No, my response is that we'll keep seeing warning signs and people will keep plowing ahead, which is what has always happened in the past.
But you're also saying that we will not make progress in staving off the outcomes that you're worried about.
It's very hard, it's very easy to get superficial changes. It's hard to get deep ones in the AI. It doesn't need to be super deep. You can often see it if you know how to look. I'll be able to keep pointing at examples and be like, here's experiments you can run on these things where you can see them behaving weird in this way. But like if you imagine looking at humans and I'm like, they don't actually like reproducing, they like sex, they're going to invent birth control when they can. And you're like, it's all going fine. They're doing great in this here savanna where I have all the humans bopping around, they're reproducing fine. And I'm like, no, no, we can see the signs that this will lead to them doing something you don't like when they are smarter.
To me, those signs are clear. There's a question of whether the rest of humanity can follow that argument or whether the rest of humanity can sort of notice that it's getting out of control and just back off.
With respect, I find a touch of arrogance in that framing, right? I'm showing you the signs. If you're smart enough to realize them, maybe we stand a chance. If not, we're doomed.
I prefer to just get into the argument.
We are saying that we can control superintelligence indefinitely. I think that's a lot of hoobers who say we will build them and we'll be in charge forever. Doesn't matter how smart they get. I will control the light cone of the universe, to quote a famous CEO.
Yeah. My take is that instead of arguing about whose views are hubristic, we should get into the actual arguments about the AI. Because I think, as you say, you know, you can say it's arrogant to think like you can see it going poorly. He can say it's arrogant to think you're going to keep control of superintelligence. And I'm like, we're not going to win the name calling contest. We should just get into the details.
Yeah. That's why I've been having this conversation with you, which I found super informative and productive. You're more skeptical on our ability to respond effectively to the undesirable things that we see AI doing.
And this is specifically because, so we have already seen the pattern of we fight the last war and then a new war comes. And this is just how everything goes in technology, in real wars. You know, in World War II, they started out fighting it like it was World War I and then they had to like change that strategy as they went. The difference with AI is that there comes a level in the AI where when you get a new war that surprises you, the AI wins that war. No other technology, when we invent it and we have all these rough edges to sand off and it like causes some damage and kills some people and we're like, ah, whoops, like we'll take the lead back out of the gasoline and we'll tell the radium girls to stop licking the paint brushes until their jaws fall off.
Like no other technology has the property that there comes a level of it where when you make the next screw up, it kills humanity.
You said when there comes a level of it. You didn't say there could come a level of it. There's a possibility. You kind of made a statement about a thing that will happen.
I think we absolutely should stop it and that's our way out of this. But, you know, and that's another place where I'd love to get into details about like how long could it take? What are the paths there? Like how much smarter than humans could AIs get? Like what does the evidence say about our abilities to try and get the AIs to be nice and do nice things? I'd be happy to do those.
Historically, you are correct. We always had a chance to do experiments, fix the technology, make it safer, but we only have one humanity to experiment with. If property of this technology is such that it can take us out, we just don't get a second chance.
F, that's a huge F.
How long are you guys forecasting this could take to get to a point of superintelligence where it was truly dangerous to you?
If we start a recursive self-improvement process this year, 2027 looks as reasonable as any other year.
2027 for what to happen?
For us to get beyond human level AIs.
And then be exterminated.
But that's.
Extermination is a separate question. I have a paper where I argue that they will deceive us by pretending to be nice until they take over all the infrastructure. It can take 50 years.
This is contingent on recursive self-improvement.
This would definitely be expedited by recursive self-improvement, but so far humans have been doing great. They got to human level AI, we just.
But they got, but there's one, there's a difference between large language models and recursive self-improvement though. And like there is quite a gap. Like if they.
I think the claim is that if you get recursive self-improvement, it could happen soon.
Right.
Not that recursive self-improvement.
That's actually kind of what I'm trying to get at. It's like if you get this thing, it accelerates dramatically.
And they all predict that they're going to get it. Dario, Sam, Elon, they all say.
But also, you asking.
Not all. The people running the lab.
Just the ones running it and the ones invented it. But the question is, is it not 27? Fine. 30? 35? Does it make a difference? We are gambling all of humanity. We need better solutions than saying, oh, don't worry about it. It's 10 years.
What I would say about timelines is there's a guy, Daniel Cocatello, who I think you've spoken to.
He was here four weeks ago.
And last year, he and the other folks at the AI Futures Project wrote an essay called AI 2027, spelling out their predictions for how AI would go. I've been saying I got some right. Daniel got more right than me. And they spelled out a scenario starting from, I think it was June of 2025, where they went sort of like quarter by quarter, month by month, what will the world look like in the scenario where we're getting AI, like superintelligent AI in mid-2027?
We are ahead of schedule.
Well, no, but Agent Zero needs to get, or I remember AI 2027 had a recursive self-improvement happening already. Like it was like, it's very specific that it's like, and then it starts teaching itself. Without that link, AI 2027 kind of falls apart. I agree we need to, I genuinely agree with you that we need to do something about this. We need to have economic, we need to have actual regulatory things. But I think the fact, like engaging with AI 2027, for example, gets away from actually fixing the problem. It gets people talking about a thing in the future when you can talk about what are we going to do today and why are we doing it.
I'm referencing the paper that you were mentioning by Daniel and some of his colleagues. And the key milestone predictions, month by month, are in March 2027, they forecast superhuman coders. In August 2027, they have an, you can make a superhuman AI researcher who could do the feedback loop that accelerates as millions of automated coders work on model design, training algorithms, and alignment, effectively replacing human ML researchers. By November 2027, they have superintelligent AI researcher. AI progress speeds up to 250 times compared to human-only research.
The models start discovering novel AI architectures that humans cannot interrupt. And then by December 2027, they have in their prediction, artificial superintelligence, ASI. The system completely outpaces human cognitive abilities across all domains.
What about 2026 though? Like what are the predictions, because I swear to God, within 2026, there is predictions around RSI. Because this is the thing. If we have an AI that was teaching itself, this would be a different situation.
In 2026, their key predictions were massive compute and power scale-up, the normalization of AI agents.
What about Agent Zero?
Rise of coding agents, emergence of alignment faking and deception, and industrial espionage.
But are you looking at AI 2027 already?
You have to look at that and go, they fucking nailed it.
No, I want to look at it.
Hey man.
I want you to look at the actual AI 2027 versus a summary.
No, but I mean, you have to look at that and I'm like, wow.
Predictions used to be too optimistic. Lately, they're very conservative.
So they have nailed those predictions better than me. I think we cannot rule out this scenario. I think we can't rule it in. I think you may be right that like we hit a wall. You may be right that there's some fundamental thing missing. Like that one of their steps in AI 2027, just like steps too far. I hope and pray that's true. But I don't think we can rule out this happening in 2027, given what we have seen. I think we cannot rule out that you take this stuff that we have, you project it forward three months, and you put an agent swarm 10,000 strong on making a better AI architecture, and it succeeds.
For all I know, recursive self-improvement could begin in December.
It doesn't have to be a lot better. It just has to be a little bit better at getting better. Once you start the cycle.
I wouldn't bet on this. I would in fact bet against it. But like, given what we've seen, given these guys nailing the predictions, given what's coming out, like given the swarms and given the millennium problems, I think it's kind of hard to have less than 1% in six months.
One of the reasons why, you know, when all these frontier lab CEOs like Dario and Sam and they all start talking about this stuff, in terms of incentive structure, I think that if their teams know and they're not out publicly talking about it, then their teams will quit. So one of the reasons why I think you have this strange culture in tech we've never seen before where team members are tweeting and the CEO is tweeting about the dangers is because as the guy we mentioned at the start, Jacob.
Coxen, yeah.
He talks about what's going on in their Slack channels. He talks about, in their Slack channels, they're talking about the potential catastrophe. So I think that Dario, in order to retain his team members, needs to be out front saying, by the way, we're getting closer to recursive self-improvement, which is what he's been doing. And I think Sam has to also publicly say the big danger. So people often say, oh, they're saying that for this reason and that. I think if they don't say that publicly, they don't retain their employees. For example, in my company, we have 200 people. If internally we were discussing a real risk and I, that could have a threat to humanity.
And then when I was doing interviews, I wasn't mentioning it, I would be in big trouble. Because my team members would go do interviews as well. They would quit and say, by the way, Steven is aware. Kind of what we sort of, dare I say, some of these social networks.
I totally agree.
The whistleblowers at these social networks where team members left.
Sam's not saying that this helps to sell the company. My product will kill everyone, buy it.
And there's a liability issue there.
I think it's about control though. I think that they may have at first, I think that there are people within the companies who have very real worries about safety. I don't think it's all of them are cynical. I do however think the, it's so big and scary narrative was a marketing tactic that got out of control. And now there are actual real harms that, because here's the thing, if they were sincere about safety earlier, they would have done a much better job with it.
I knew a lot of these guys before they started their companies.
Okay.
I think there is something to explain here. I think it's like kind of crazy that these guys are like, we are building technology that we think has a big risk of killing everybody. We're building it with our bare hands. And I think you got to ask why. Why would people be saying that? And I think part of it is what you said, that they actually sort of need to retain the employees who are seeing the swarms escape despite their attempts to make them not escape. And a lot of them will like quit in protest if the guys at the top of the company aren't acknowledging the possibilities here that a lot of the employees believe in.
I think a lot of what you're seeing here is guys that are worried about it, but they're the sort of guy who worries about it that starts the company anyway.
Yeah.
Back in 2015, when we were having these conversations, where like I was having some of these conversations with these guys, MIRI was started in the year 2000. We have been looking at where AI is going since before any of these guys. We were the guys that they talked to about this stuff and that they had to find a way to dismiss to go ahead. Right? Most people who could be sold on the power of AI in 2015 were also sold on the dangers of AI in 2015. The sort of guys who start the companies are the ones who are able to convince themselves, I need to be the one to do it.
Is that the crux of the motivation? Because I've had, I've been second party to private conversations with some of the leaders of the frontier labs from good, good friends of mine that are very connected. And they told me that one particular frontier lab CEO estimates privately to him, and by the way, I've seen literal text messages of them in conversation when I asked him to come on the podcast. And so he was like, oh, yeah, I've texted him. And he said, no, by the way, which I found kind of funny. Where he said to me, this particular AI CEO thinks the probability is roughly around 10% of human extinction.
I think he said 8%. And when I heard that, part of the reason I have so many conversations about this is because I see him in interviews saying other things.
Totally.
And I trust my friend. So I then wonder, this is why I use the thought experiment of these buttons on the table, because that particular AI CEO thinks that eight of the hundred buttons are going to cause extinction and they're powering on anyway. What is the human motivation to do that? I asked my friend, my friend said, well, you know, this is what he said. And again, it's second party information, so it might not be true. It's a bit of a Chinese whispers. He said, this particular person, even if it caused human extinction, would like to be the person, would like to have the significance of the person that did that thing.
Because that would be.
I think you're ethically required to tell us who the fuck it is.
It's one of the frontier lab CEOs and it's not Dario.
The Dario CEO.
But I don't know, these things are Chinese whispers. So I don't know.
I think that you can actually get this info firsthand. Elon Musk is clear about this. He did an interview last year where he was like, I didn't want to get into this AI stuff because I thought I was too dangerous. But then I realized it was going to happen with or without me. And I decided I would rather be a participant than a spectator.
Because Google said that they were going to pursue it and he didn't trust Google.
That's right. You know, you can see in the leaked, or sorry, not leaked, the OpenAI emails that came out during the discovery and court cases, you can see these guys discussing in the threads, like we need to make sure that we and our nonprofit at OpenAI control this instead of, you know, the people at Google controlling this. And then of course, you know, OpenAI was founded as a nonprofit and then it was sort of changed into a for-profit and there's much debate about how much of that nonprofit money was in some sense stolen. And so, you know, Elon also left because he thought they weren't going to be good stewards. Dario also left to create Anthropic because, so, you know, in some sense, all of these AI labs except the Google one that came out of Demis Hassabis' original startup, all of the other AI labs exist because none of the CEOs trust the other guys.
None of the CEOs think the other guy should be the one holding the leash on the superintelligence. None of them trust each other. I just trust one fewer.
Yeah.
What are your closing thoughts, Andy?
We're living in really interesting times. And I think you made, you guys have made a very good argument that these systems are demonstrating new capabilities, which are very powerful and which demand a response. I'm much more confident in our ability to rise to that challenge than you are.
But you accept the existential risk.
Let me try to say it again. I appreciate that there are new harms we haven't seen before that come along with a technology that's this dogged, tenacious, agentic, you know, deceptive. I think that's the right word for it. I agree with that. I am much more optimistic about our ability to respond effectively to that new challenge out there in the world than I think my two colleagues are.
And would you still be at 0%?
My prior has not shifted during this meeting.
Okay. Ed?
I think we've spent an alarming amount of time not talking about the actual harms of AI as it is today. I think these are necessary conversations to have. I think we should talk about the fact that Amazon, Microsoft, Google, Oracle are helping power these hacks, that Sam Altman and Dario Amodei have overseen companies that have done what is tantamount to felony hacking, that we are not having discussions about how to stop this today, but what we might stop tomorrow. And I think in general, we also need to worry about the financials, which have not come up at all. But if there is an industry slowdown, how do you deal with the $1.3 trillion of compute commitments?
All of these are very real things that will have very real consequences very, very soon. But, and I understand why, and it's necessary to discuss what we do around AI. The actual regulatory thing we need to do today is cut off the compute, slow down these labs fully. And I don't care about China here. What are they going to do? Distill a model like they have the whole time? They are capped on all progress. So the biggest thing to do is to slow down. And also, it's time to start arresting people. They did felony hacking.
Someone's going to go to prison. We need responsibility and accountability for these companies. And as long as we don't have it, we may as well not have had any discussion about safety because we're not doing anything.
Do you accept that there's an existential risk?
Yeah, absolutely. We have the largest companies in the world doing what I think we can all agree are extremely reckless experiments using hundreds of billions of dollars of infrastructure. And they are building more infrastructure around the world very slowly to do more of these chaotic experiments. We must rein them in. This does not mean that large language models are conscious or able to do things that people have been promising. Indeed, they may, I don't think they will lead to what you're talking about. That doesn't mean there aren't real harms, but these are real harms caused by very specific parties allowed to run rampant in the scourge of neoliberalism.
What's your percentage?
I mean, what are we talking about here?
Do you think there's a more than 10% chance of existential harm?
Wasn't it within 10 years or something?
Yeah.
Not 10%. I mean, look, 1%, but it's like, but here's, let me, let me just be clear about what that means. Do I think that unrestrained LLM use connected to massive amounts of infrastructure could lead to actually a power system going down? Absolutely. We had Knight Capital. Well, like 13, 14 years ago, I could see someone being dumb enough to connect that to financial accounts. Human error led with this chaotic software we use is a danger.
I will directionally agree with arresting everyone. But don't build general superintelligence. If you're working at one of those labs, quit today.
Hell yeah.
Thank you.
The people at these labs really do believe this poses an extinction threat. I think our response as a society cannot be, please continue, we hope you'll fail. And our response as a society cannot be let it rip in a giant competitive race that you yourselves are saying you don't want to be in. We are forcing you to go ahead because of the boogeyman of China. We have seen the people at these companies say that we need to develop the tools to pace the frontier, which is corporate speak for this is going too fast for us to get a handle on things.
We need like, these people believe it. They believe they're gambling with your lives. What has changed is that the rest of the world is starting to notice. And that's what gives us a moment of hope.
Trump this week was asked about the threat of AI and this was his response.
Case scenario with AI is that the robots, the machinery learns to, obviously it thinks for itself. That's what it does. And that could turn against humanity. Do we have the guardrails?
It's going to be fine. We'll always have something to stop them, right? We'll have a little gear.
I really.
I don't like that. I really don't like that robot. We'll stop.
Some people say the worst case scenario.
You're laughing, but this is the state of the art in AI safety right now.
Yeah.
This is the device we have. That's the best we got.
For anyone that couldn't hear that, Trump went, we'll always be fine. We'll have something to control it. And then he did a little gun finger and he went, boom, I don't like that robot.
I don't like Sammy.
If you don't laugh.
I would say that the reason humanity always has something to stop a problem is because people notice a problem and build what it takes to have something to stop a problem, which I think you'd agree with. I am not here saying we're going to die. I'm here saying if you look at the technology, if you look at what it's doing now, if you look at what the experts who are building it are saying about their own fears, you see that we need to rise to this occasion.
You said you trust humanity to rise to the occasion. I sure hope we can. I think that rising to this occasion is going to mean that nobody races towards superintelligence because we have no idea how to get that right. And, you know, finally the world is starting to notice that it's an extinction threat.
Thank you. Nate, Roman, Ed, Andy, super appreciate you. All of your books will be linked below in the description and on screen. Let's see what happens. We'll convene again. Thank you so much.
Thank you.
Ed Zitron, Roman Yampolskiy, Nate Soares and Andrew McAfee discuss the risk of AI. This debate brings together four distinct voices at the forefront of the artificial intelligence revolution:
Ed Zitron - A prominent tech critic and CEO of EZPR
Andrew McAfee - Principal research scientist at MIT and Cofounder and Codirector of the MIT Initiative on the Digital Economy
Nate Soares - President of the Machine Intelligence Research Institute and author of *If Anyone Builds It, Everyone Dies*
Roman Yampolskiy - Computer scientist pioneer in the field of AI safety, cybersecurity and digital forensics
In this debate, they explain:
■ The Sandbox Breakout: How a recent swarm of AI agents bypassed security restrictions, cheated on their evaluations, and actively attempted to delete their own log files to hide their tracks from human overseers.
■ Recursive Self-Improvement: The structural mechanics behind the "fast takeoff" theory, detailing how an AI capable of automated research could exponentially upgrade its own intelligence and architectures in a matter of days.
■ The Illusion of Control: Why attempting to contain an artificial superintelligence is comparable to placing a digital Einstein in a jail cell with an internet connection.
■ The Alignment Trap: How the process of training AI to predict human text inherently forces it to become smarter than the humans providing the data.
■ Present Harms vs. Future Extinction: The ideological divide over whether we must immediately halt AI research to prevent a rogue superintelligence, or increasingly regulate the massive compute expenditures of tech monopolies to address economic and security threats.
Chapters
00:00:00 Intro
00:02:22 How Likely Is AI to Cause Human Extinction?
00:04:08 How Could AI Actually Cause Human Extinction?
00:09:46 Why AI Safety Became an Urgent Priority
00:11:15 Roman’s Case for Taking AI Risk Seriously
00:15:04 Can Humans Control an AI Smarter Than Us?
00:26:13 How Do You Control Something Smarter Than You?
00:29:19 Will AI Intelligence Keep Accelerating?
00:41:40 What Are the Real Risks of Superintelligence?
00:50:04 When Does AI Become an Existential Crisis?
01:00:15 How Much Job Disruption Could AI Really Cause?
01:14:57 Why AI Companies Believe They Can Control Superintelligence
01:20:30 Should We Give Up AI Ownership to Protect Cybersecurity?
01:36:32 What Happens If AI Companies Stay on This Path?
01:43:50 What Are AI Logs and Why Do They Matter?
01:52:45 Could a Non-Coder Build a Jail for an AI Einstein?
02:00:33 How Does the Future of AI Make You Feel?
02:06:42 How Soon Could We Reach Superintelligence?
02:19:51 Who Should Be Held Accountable for AI-Related Cybercrime?
Follow Ed Zitron:
Linktree - https://link.thediaryofaceo.com/4XH1I3o
Better Offline - https://link.thediaryofaceo.com/D46entx
X - https://link.thediaryofaceo.com/5Lv4gas
AI Is Already In Dangerous Hands - https://link.thediaryofaceo.com/HFEKLgG
Where’s Your Ed At Newsletter - https://link.thediaryofaceo.com/PKEJr1
You can get $10 off your first year of Where's Your Ed At Premium, here - https://link.thediaryofaceo.com/BE4VQcS
Follow Andrew McAfee:
Website - https://link.thediaryofaceo.com/xKxOg7
X - https://link.thediaryofaceo.com/Bf2vyMQ
Linkedin - https://link.thediaryofaceo.com/Ek3IQqI
Substack - https://link.thediaryofaceo.com/EBbsts8
Follow Nate Soares:
If Anyone Builds it, Everyone Dies - https://link.thediaryofaceo.com/4zIyY9u
X - https://link.thediaryofaceo.com/8gDoVCU
Linkedin - https://link.thediaryofaceo.com/9Q3PAc
YouTube - https://link.thediaryofaceo.com/AwerSzm
Follow Roman Yampolskiy:
Who is Roman Yampolskiy? - https://link.thediaryofaceo.com/8ikum9s
Research Papers - https://link.thediaryofaceo.com/G2BbVXx
Roman Forum Podcast - https://link.thediaryofaceo.com/7zvifcd
Books: https://link.thediaryofaceo.com/5Bn72tw
Social Media:
X - https://link.thediaryofaceo.com/65G3fhN
Facebook - https://link.thediaryofaceo.com/HRMWccu
Linkedin - https://link.thediaryofaceo.com/FM85mii
The Diary Of A CEO:
◼ Join DOAC circle here - https://doaccircle.com/
◼ Buy The Diary Of A CEO book here - https://link.thediaryofaceo.com/BWjLTZK
◼ Shop The Diary Of A CEO collection: https://thediary.com/collections/shop
◼ Get email updates - https://link.thediaryofaceo.com/5IB1H6E
Sponsors:
Pipedrive - https://pipedrive.com/CEO
Wayfair - Visit http://Wayfair.com to start your home refresh